Command Palette
Search for a command to run...
Omni-IO Skills: Harnessing Your Agent Omni-Native
Omni-IO Skills: Harnessing Your Agent Omni-Native
Yanlin Li Mingyang Hao Shengqiong Wu Hao Fei Mong-Li Lee Wynne Hsu
Abstract
General-purpose agents can plan, reason, and act over long horizons, yet their production capabilities remain fragmented across text, images, audio, video, documents, 3D assets, and code. Extending a foundation model to additional modalities ties capability growth to costly model updates, while assembling specialist models and tools leaves unresolved how procedures, dependencies, intermediate assets, and cross-turn revisions should be coordinated. We present Omni-IO Skills, a plug-and-play Agent Harness that makes existing agents omni-native through hierarchical Skills, a standardized multimodal execution interface, dependency-aware orchestration, and a persistent Asset Registry. Multi-asset workflows are represented as Declare Execution Graphs, which schedule independent operations concurrently and register successful outputs for downstream and cross-turn reuse across replaceable execution backends. Its 27 Skills cover 38 representative tasks spanning seven artifact modalities and four capability families: understanding, generation, reasoning, and retrieval. On UniM-90, the harness raises the input-support rates of GPT-5.6 Sol and Claude Sonnet 5 from 40.00% and 38.89% to 100%, while increasing relative Semantic–Quality Coupled Score from 26.99 to 74.94 and from 27.82 to 77.78, respectively; Strict Structure Score reaches 100.00 and 99.78. These results establish harness-level capability composition as a practical route to broad, evolvable Omni systems without changing the host agent’s reasoning core.
One-sentence Summary
Researchers from the National University of Singapore and the University of Oxford propose Omni-IO Skills, a plug-and-play Agent Harness that combines hierarchical Skills, standardized multimodal execution, dependency-aware orchestration via Declare Execution Graphs, and a persistent Asset Registry, with 27 Skills covering 38 tasks across seven modalities and raising the input-support rates of GPT-5.6 Sol and Claude Sonnet 5 on UniM-90 from 40.00% and 38.89% to 100%.
Key Contributions
- Omni-IO Skills is a plug-and-play Agent Harness that makes general-purpose agents omni-native without altering their reasoning core, using hierarchical Skills, a standardized multimodal execution interface, dependency-aware orchestration, and a persistent Asset Registry.
- It represents multi-asset workflows as Declare Execution Graphs that schedule independent operations concurrently and register successful outputs for downstream and cross-turn reuse across replaceable execution backends, with 27 Skills covering 38 representative tasks across seven artifact modalities and four capability families: understanding, generation, reasoning, and retrieval.
- On UniM-90, Omni-IO Skills raises input-support rates for GPT-5.6 Sol and Claude Sonnet 5 from 40.00% and 38.89% to 100%, increases relative Semantic-Quality Coupled Score from 26.99 to 74.94 and from 27.82 to 77.78, and reaches Strict Structure Scores of 100.00 and 99.78.
Introduction
Real-world Omni workflows span lecture recordings, documents, visual design, slides, audio, video, 3D assets, and code, so agents must receive and produce interleaved modalities while preserving semantic and asset continuity. Omni foundation models have improved unified understanding and generation, but scaling more modalities into one backbone forces tradeoffs in representations, objectives, tokenization, fidelity, and update cycles. General-purpose agents such as Codex and Claude Code provide strong reasoning and planning, yet their end-to-end production surface remains centered on software and knowledge work, while model-coordination systems and Agent Skills can delegate to specialists or package procedures without fully solving capability selection, artifact transfer, failure isolation, and cross-turn recovery. The authors introduce Omni-IO Skills, a plug-and-play harness that leaves the host agent unchanged and adds hierarchical Atomic, Expert, and Scenario Skills, dependency-aware execution, replaceable backends, and a persistent Asset Registry, enabling existing agents to complete multimodal workflows without retraining.
Method
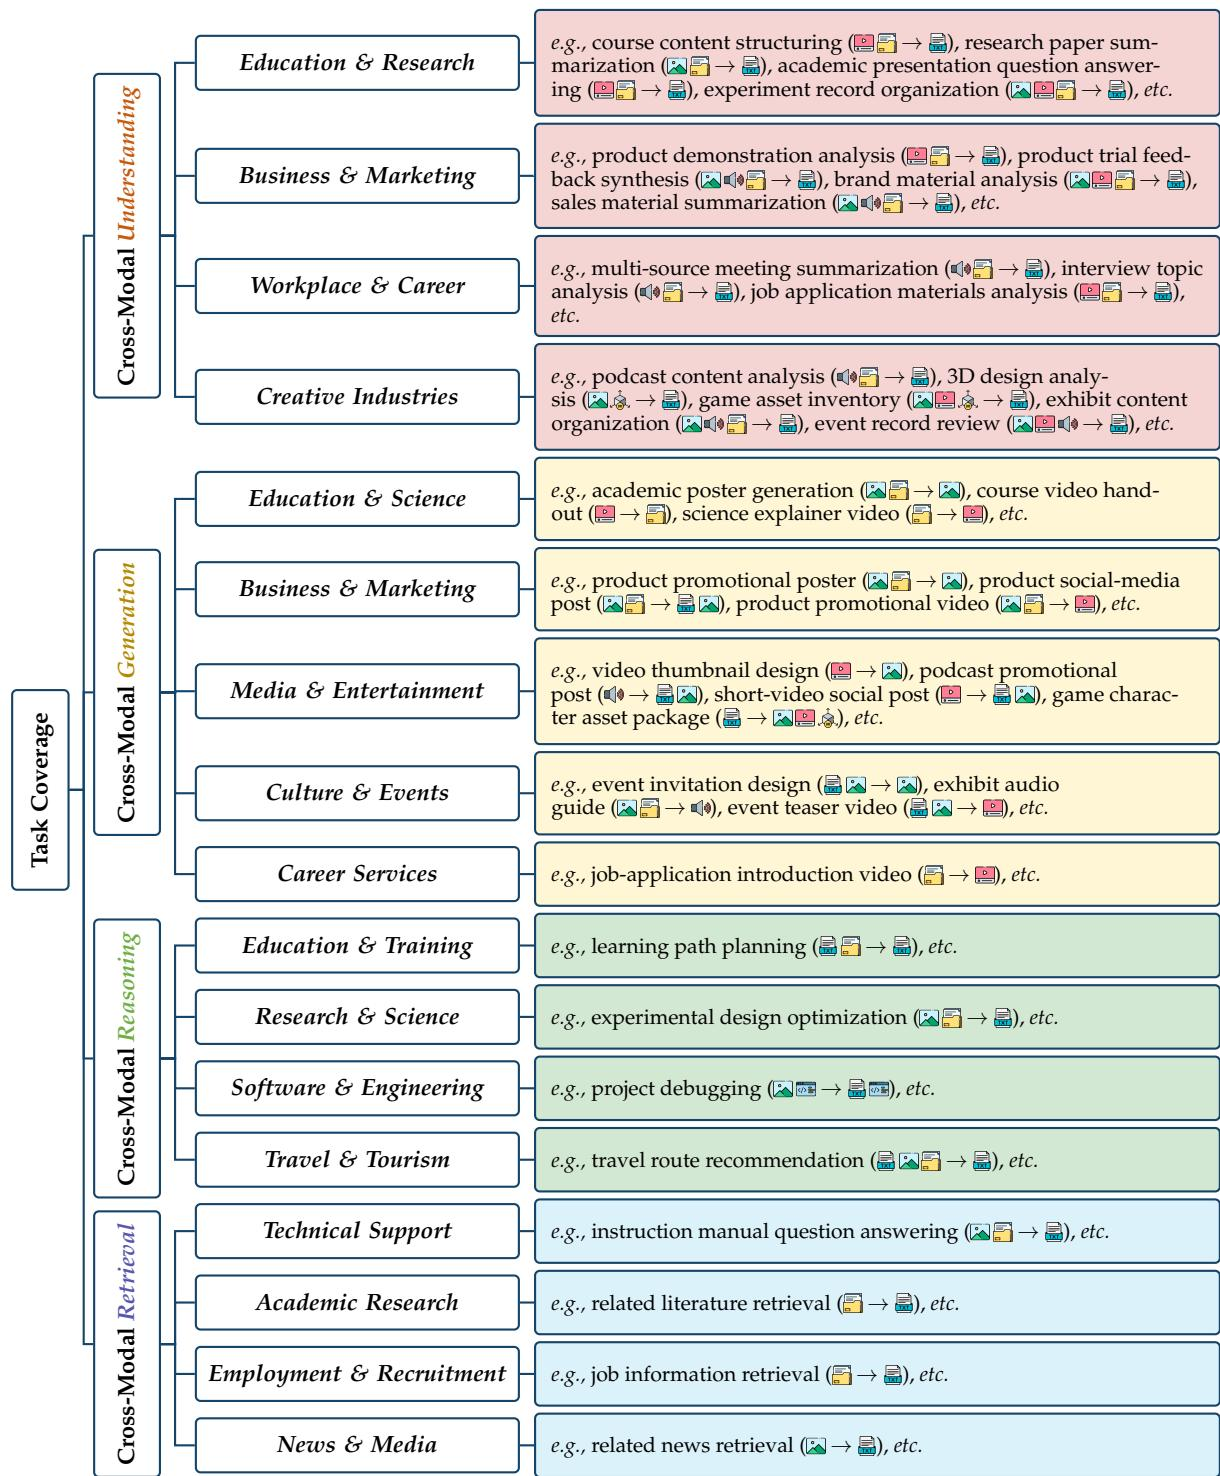
The authors design Omni-IO Skills to handle application-facing tasks where source material, intermediate assets, and deliverables span multiple media types. The system supports cross-modal understanding, generation, reasoning, and retrieval across seven artifact types: Text, Image, Video, Audio, Document, 3D, and Code. An icon on the left of an arrow denotes an input, while an icon on the right denotes an output, illustrating how tasks consume or produce multiple artifact types.
To manage these complex workflows, the system adopts a four-layer architecture positioned between the host agent and external multimodal tools. This structure separates task knowledge, tool interfaces, service implementations, and persistent outputs, allowing the host agent to plan multimodal tasks without coupling an application workflow to a particular provider or workspace path.
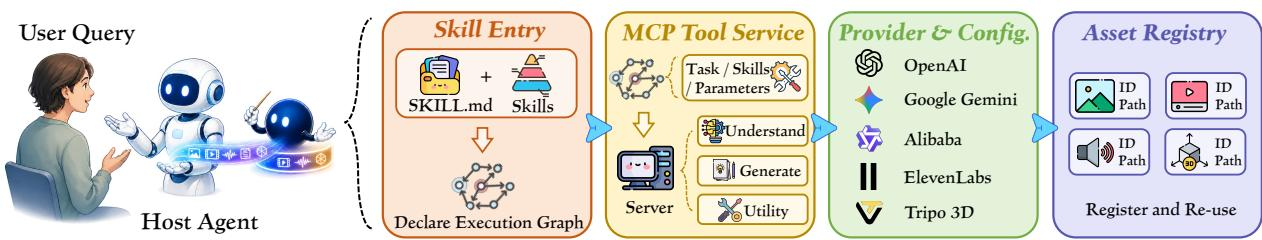
The Skill Entry layer exposes a unified task interface to the host agent. It organizes reusable procedural knowledge into three hierarchical levels based on task granularity and compositional scope.
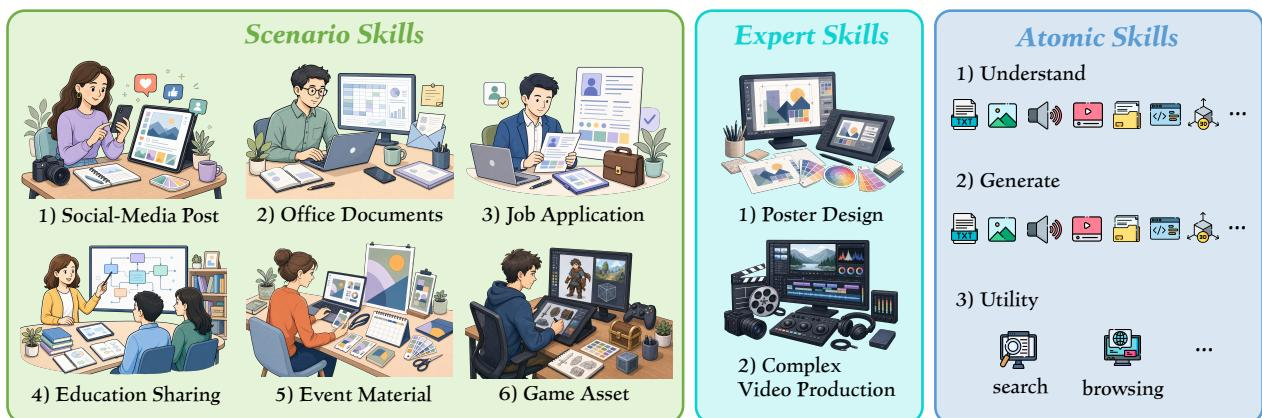
Atomic Skills perform single, independently invocable operations. Expert Skills target a specific final deliverable by organizing multiple atomic operations into a complete workflow, such as poster design or complex video production. Scenario Skills address broader application contexts, determining required deliverables and coordinating the appropriate Expert or Atomic Skills.
Skills at all levels follow a shared declarative representation s=⟨cs,Is,Ps,Os,Hs⟩, where cs describes applicability conditions, Is and Os define inputs and outputs, P records the execution procedure, and Hs identifies relationships to other Skills. Upon receiving a request, the system selects the relevant Skill and recursively expands it until the steps are executable. Higher-level Skills are replaced by their constituent lower-level Skills, forming a Declare Execution Graph (DEG).
The MCP Tool Service layer converts semantic task specifications into standardized executable operations. It groups external capabilities into understanding, generation, and utility tools. Each externally executed DEG node is submitted through a common contract containing its task type, prompt, parameters, and dependency-resolved asset inputs. This layer also defines the boundary between external tool execution and host-native execution, ensuring that both routes follow the same dependency semantics.
The Provider and Configuration layer separates a tool capability from the specific service implementation used to execute it. For each task type, it maintains bindings to the corresponding tool, provider, model, credentials, default parameters, and fallback policies. This separation allows for implementation-level substitution without rewriting the procedural knowledge encoded by the Skills.
The Asset Registry provides a shared data abstraction for all artifacts. A registered asset is represented as a=⟨asset_id,type,subtype,path,description,params,turn_id,source_asset_id⟩. This globally unique identifier allows upper layers to reference assets independently of their physical file paths. Records are persisted in an append-only JSON registry to maintain traceability and support cross-turn reuse.
The runtime workflow jointly organizes control flow and asset flow. Upon receiving a user request, the Skill Entry layer selects and expands Skills into executable tasks, which are instantiated as nodes in a DEG.
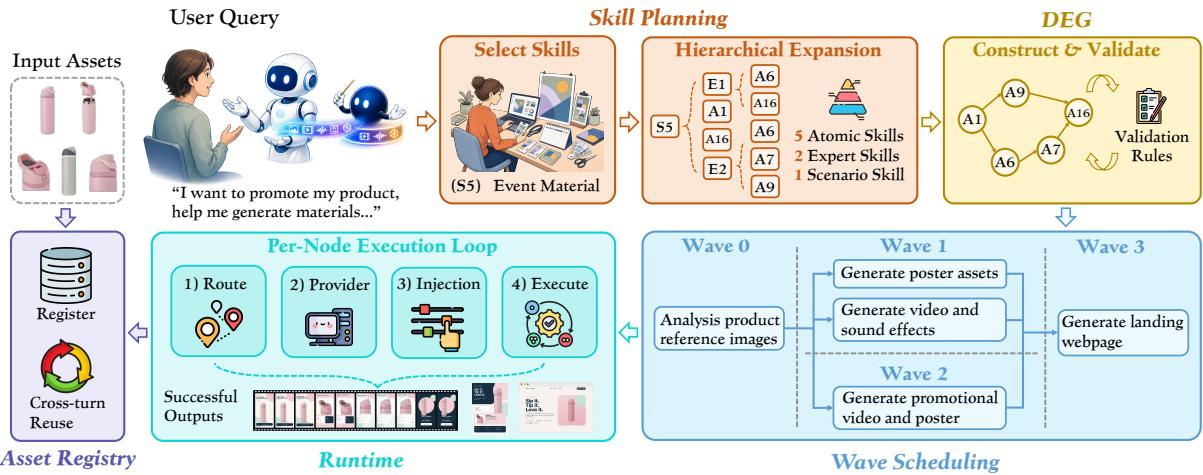
Before execution, the DEG undergoes structural validation to ensure all dependencies resolve and the graph is acyclic. Valid graphs are scheduled in successive Waves. Pending nodes whose predecessors have all completed form the next Wave, allowing independent nodes to execute concurrently. For each executable node, the MCP Tool Service selects the appropriate tool, and the Provider and Configuration layer resolves the specific provider and parameters. Upstream outputs are injected as inputs for downstream tasks. Once a node completes successfully, its output is registered in the Asset Registry, making it available for downstream nodes or future requests.
Experiment
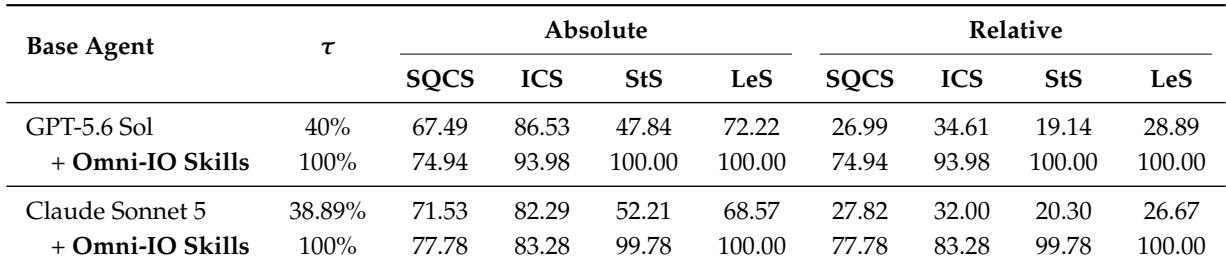
The evaluation compares GPT-5.6 Sol and Claude Sonnet 5 with and without Omni-IO Skills on UniM-90, a multimodal subset covering text, image, audio, video, document, code, and 3D tasks. Adding Omni-IO Skills enables both agents to process all input modalities and yields consistent gains in semantic quality, interleaved coherence, and output structure. Qualitative case studies on art tutorial generation and product promotion further show that the skills support coordinated multimodal understanding, generation, and task orchestration while preserving consistency across outputs.
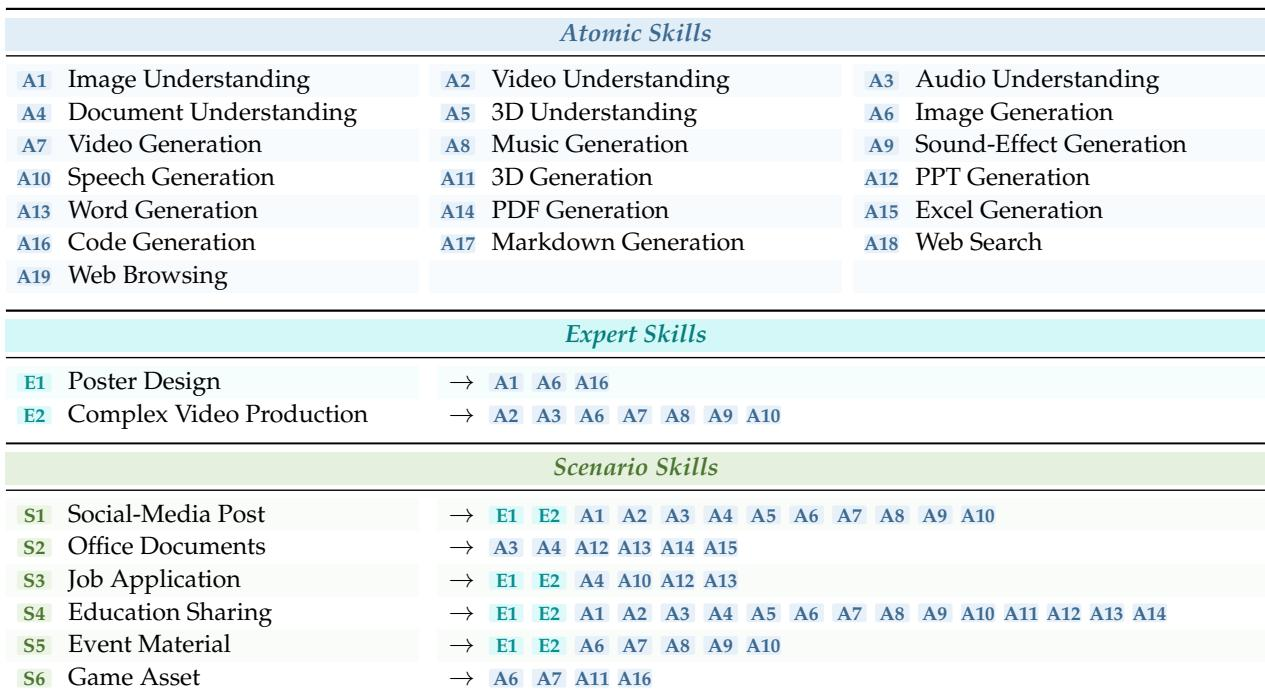
Omni-IO Skills are organized as a three-level hierarchy in which higher-level scenario and expert skills expand into atomic operations. The implemented atomic skills cover multimodal understanding, generation, and web browsing, including visual, audio, document, 3D, text, and code capabilities. This hierarchical composition supports reusable lower-level capabilities and shared intermediate artifacts across complex deliverables. Atomic skills span multimodal understanding across images, video, documents, and 3D, and generation across video, music, speech, 3D, word, PDF, code, and markdown. Higher-level scenario and expert skills recursively expand into atomic skills, allowing complex workflows to reuse lower-level capabilities while shared inputs and intermediate results are represented once.
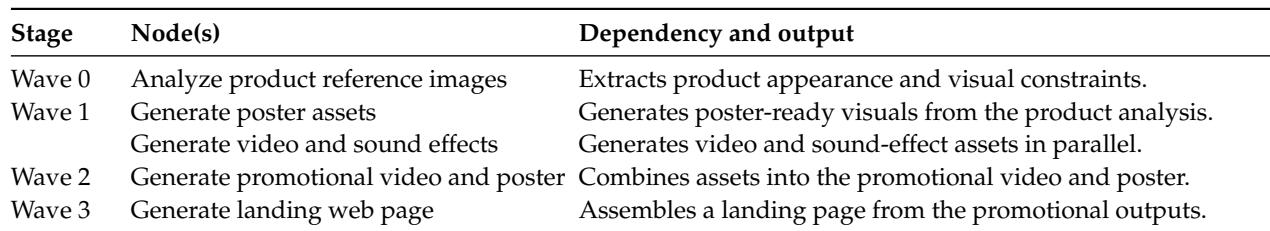
A product-promotion request is decomposed into a four-wave dependency graph. Product reference analysis runs first, poster and video/sound-effect assets are generated in parallel next, promotional video and poster are assembled third, and landing page generation runs last. Completed upstream assets are registered so later revisions can reuse them and re-execute only the affected downstream task. Product reference analysis runs first and extracts product appearance and visual constraints before any asset generation begins. Poster assets and video/sound-effect assets are generated in parallel in the second wave, then combined into promotional video and poster in the third wave, with landing-page generation last. When a new landing-page style is requested, registered product analysis and promotional assets are reused and only the landing-page task runs again.
Omni-IO Skills consistently improves both GPT-5.6 Sol and Claude Sonnet 5 on UniM-90. Input support becomes complete for both base agents, and relative semantic quality, interleaved coherence, strict structure, and lenient structure metrics all rise substantially. The gains show broader modality coverage and stronger output-structure control. Adding Omni-IO Skills raises input support to 100% for both base agents, compared with around or below 40% without it. Relative semantic quality and interleaved coherence improve substantially, and structure scores become near-perfect across both base agents.
The experiments examine Omni-IO Skills as a three-level hierarchy of atomic and higher-level skills spanning multimodal understanding, generation, and web browsing, and evaluate it through a product-promotion workflow with a four-wave dependency graph. The workflow validates reuse of upstream artifacts and selective re-execution when only a downstream task changes. On the UniM-90 benchmark, adding Omni-IO Skills to GPT-5.6 Sol and Claude Sonnet 5 yields complete input support, stronger semantic quality and interleaved coherence, and near-perfect structure control, indicating broader modality coverage and more reliable output formatting.