Command Palette
Search for a command to run...
WorldFoundry: Towards Unified Infrastructure for World Intelligence
WorldFoundry: Towards Unified Infrastructure for World Intelligence
Abstract
Visual generative models increasingly blur the line between synthesizing observations and simulating environments. Yet visual plausibility alone does not constitute successful world modeling: compelling outputs may lack persistent state, physical dynamics, or causally consistent responses to interactions. The absence of a shared operational basis, together with perception-centric benchmarks and fragmented workflows, obscures the distinction between generative foundation models and generative world models and hinders reproducible assessment of dynamics, controllability, and interactive utility. We define a generative world model as a predictive dynamical system that maintains a persistent, history-conditioned representation of an environment, updates that representation in response to actions or interventions, and generates temporally coherent trajectories that reflect outcomes under observed and counterfactual interventions. From this definition, we derive an intelligenceoriented framework spanning perceptual grounding, persistent state modeling, controllable transformation, dynamics-aware prediction, and closed-loop interaction. We further present WorldFoundry, open-source infrastructure for reproducible inference and evaluation across video, 3D and 4D, embodied action, and interactive world systems. WorldFoundry unifies model and benchmark discovery, runtime and asset preparation, execution orchestration, artifact management, and interactive visualization, while modality-specific adapters preserve native inputs, execution semantics, output representations, and evaluation protocols. Explicit manifests, durable artifact contracts, and evidence-aware scorecards separate execution readiness from evaluative claims, making each claim traceable to its supporting artifacts. The current catalog contains 270 model entries, 74 benchmarks, and 62 registered metric entries, with integration readiness and execution evidence recorded separately for each entry. By coupling world modeling with evidence-grounded executable infrastructure, WorldFoundry enables reproducible comparison of persistent, controllable dynamics across heterogeneous systems, advancing the field from perceptual synthesis toward measurable world intelligence.
One-sentence Summary
Researchers at OpenEnvision, NTU, Princeton, et al. propose WorldFoundry, an open-source infrastructure that defines generative world models as predictive dynamical systems and unifies reproducible inference and evaluation across video, 3D/4D, embodied action, and interactive systems through explicit manifests, artifact contracts, and evidence-aware scorecards, thereby advancing measurable world intelligence.
Key Contributions
- The paper defines a generative world model as a predictive dynamical system that maintains persistent, history-conditioned state, updates that state under actions or interventions, and generates temporally coherent trajectories reflecting observed and counterfactual interventions, using this definition to distinguish generative world models from generative foundation models.
- The paper derives an intelligence-oriented evaluation framework spanning perceptual grounding, persistent state modeling, controllable transformation, dynamics-aware prediction, and closed-loop interaction, shifting assessment from individual output quality to the behavior of the full world-modeling loop.
- WorldFoundry is introduced as open-source infrastructure for reproducible inference and evaluation across video, 3D and 4D, embodied action, and interactive systems, with modality-specific adapters, explicit manifests, artifact contracts, and evidence-aware scorecards; it records 270 model entries, 74 benchmarks, and 62 registered metric entries with integration readiness and execution evidence tracked separately.
Introduction
Recent generative modeling has moved beyond synthesizing individual objects or scenes toward modeling worlds that evolve over time and respond to interventions, requiring systems that perceive observations, infer structured state, predict dynamics, and support interactive outputs. Video generators, 3D and 4D scene representations, and embodied policies each address complementary parts of this problem, but incompatible representations, runtimes, interfaces, and evaluation protocols make capabilities difficult to compose, reproduce, and measure; prior infrastructure efforts remain partial. The authors therefore define a generative world model as a learned, history- and control-conditioned dynamical system that maintains a persistent environmental state, evolves it under interventions, and assimilates observational feedback, using loop closure rather than visual plausibility as the qualifying criterion. They contribute WorldFoundry, an open-source system for integrating, executing, and evaluating video, 3D, 4D, interactive world, and embodied-action models, with 270 integrated models and over 100 benchmark and metric implementations validated through documented workflows.
Method
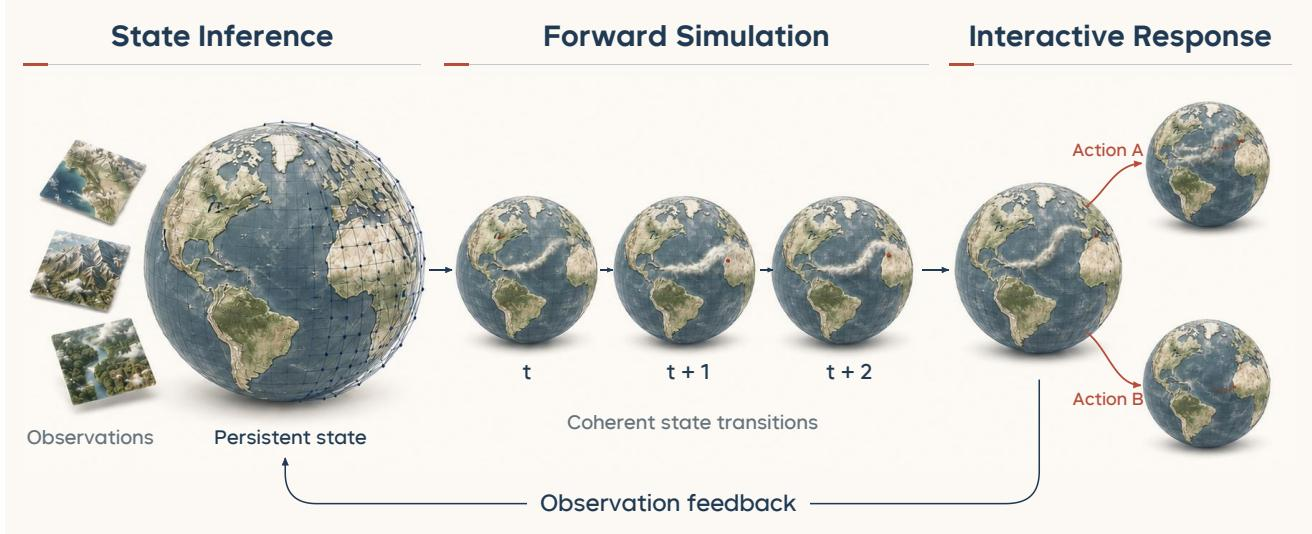
The authors characterize world modeling by three tightly coupled operations: state inference, forward simulation, and interactive response. A generative world model is defined as a learned, history and control conditioned latent dynamical system that infers and maintains a persistent environmental state, evolves that state under endogenous dynamics and external interventions, and assimilates feedback to generate coherent future trajectories. To assess these capabilities reproducibly, the authors introduce WorldFoundry, an open source infrastructure organized around a common lifecycle of discovery, runtime preparation, execution, inspection, and evaluation.
As shown in the framework diagram, WorldFoundry comprises five primary components that bring heterogeneous visual generation and world modeling systems into a coherent operational framework.
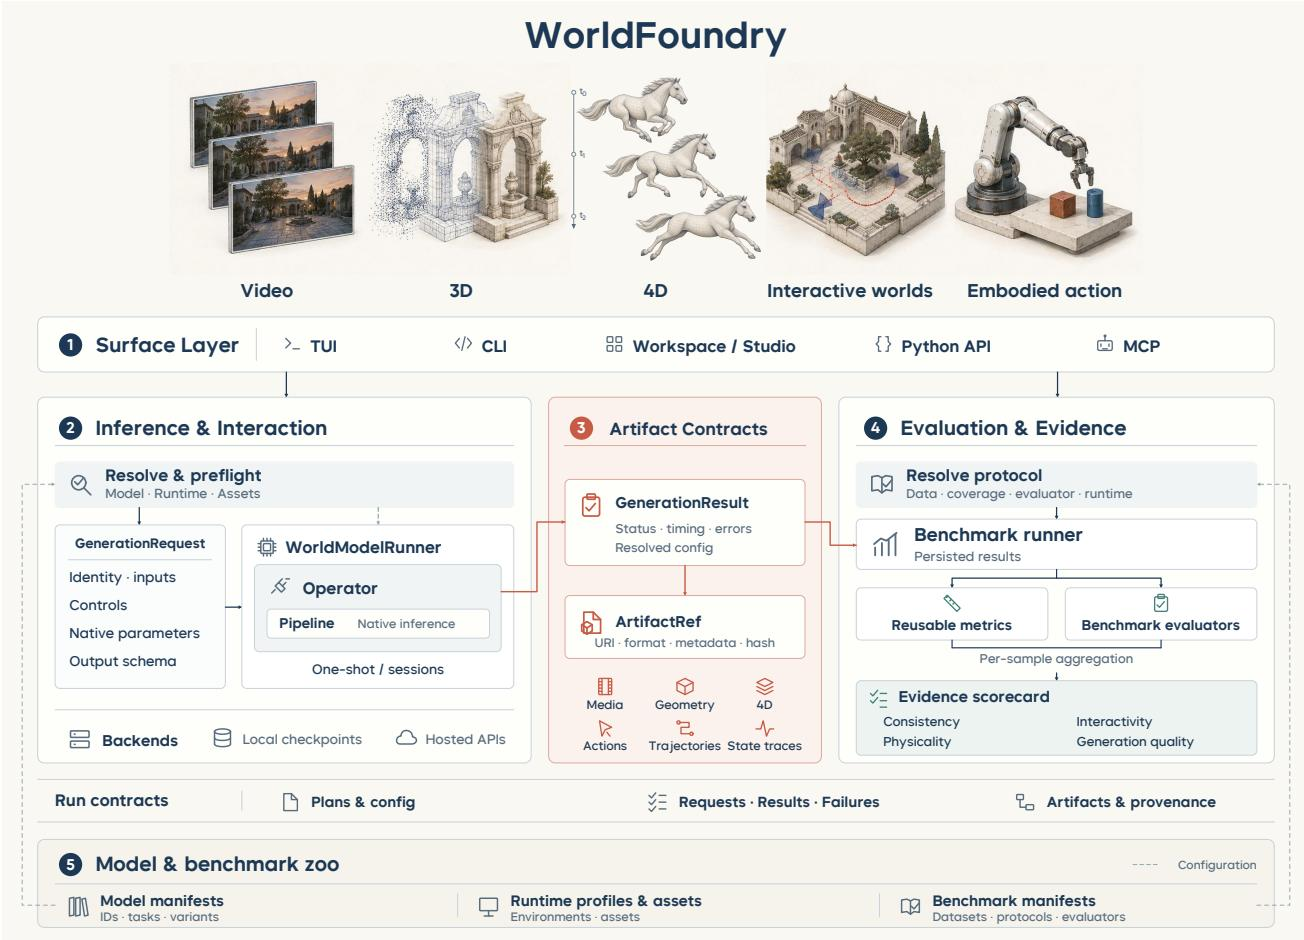
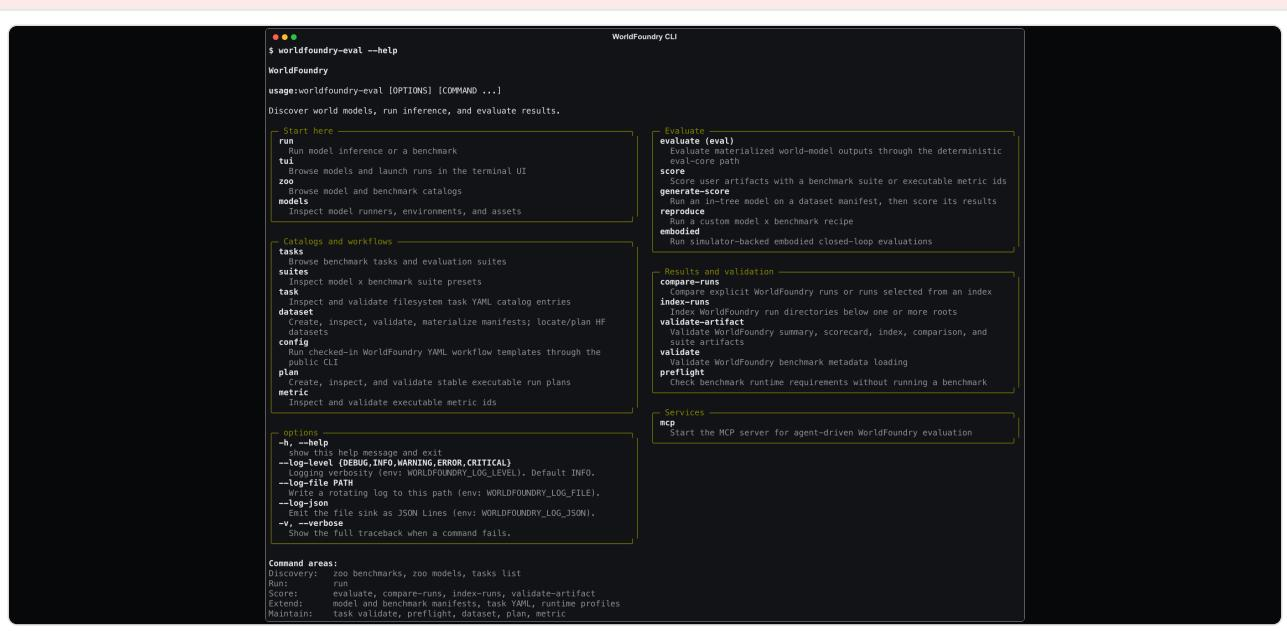
The Surface Layer provides consistent user facing access through multiple interfaces that share a single orchestration path. The command line interface covers discovery, preparation, inference, evaluation, validation, and reporting, and is designed for automated experimentation and reproducible benchmarking.
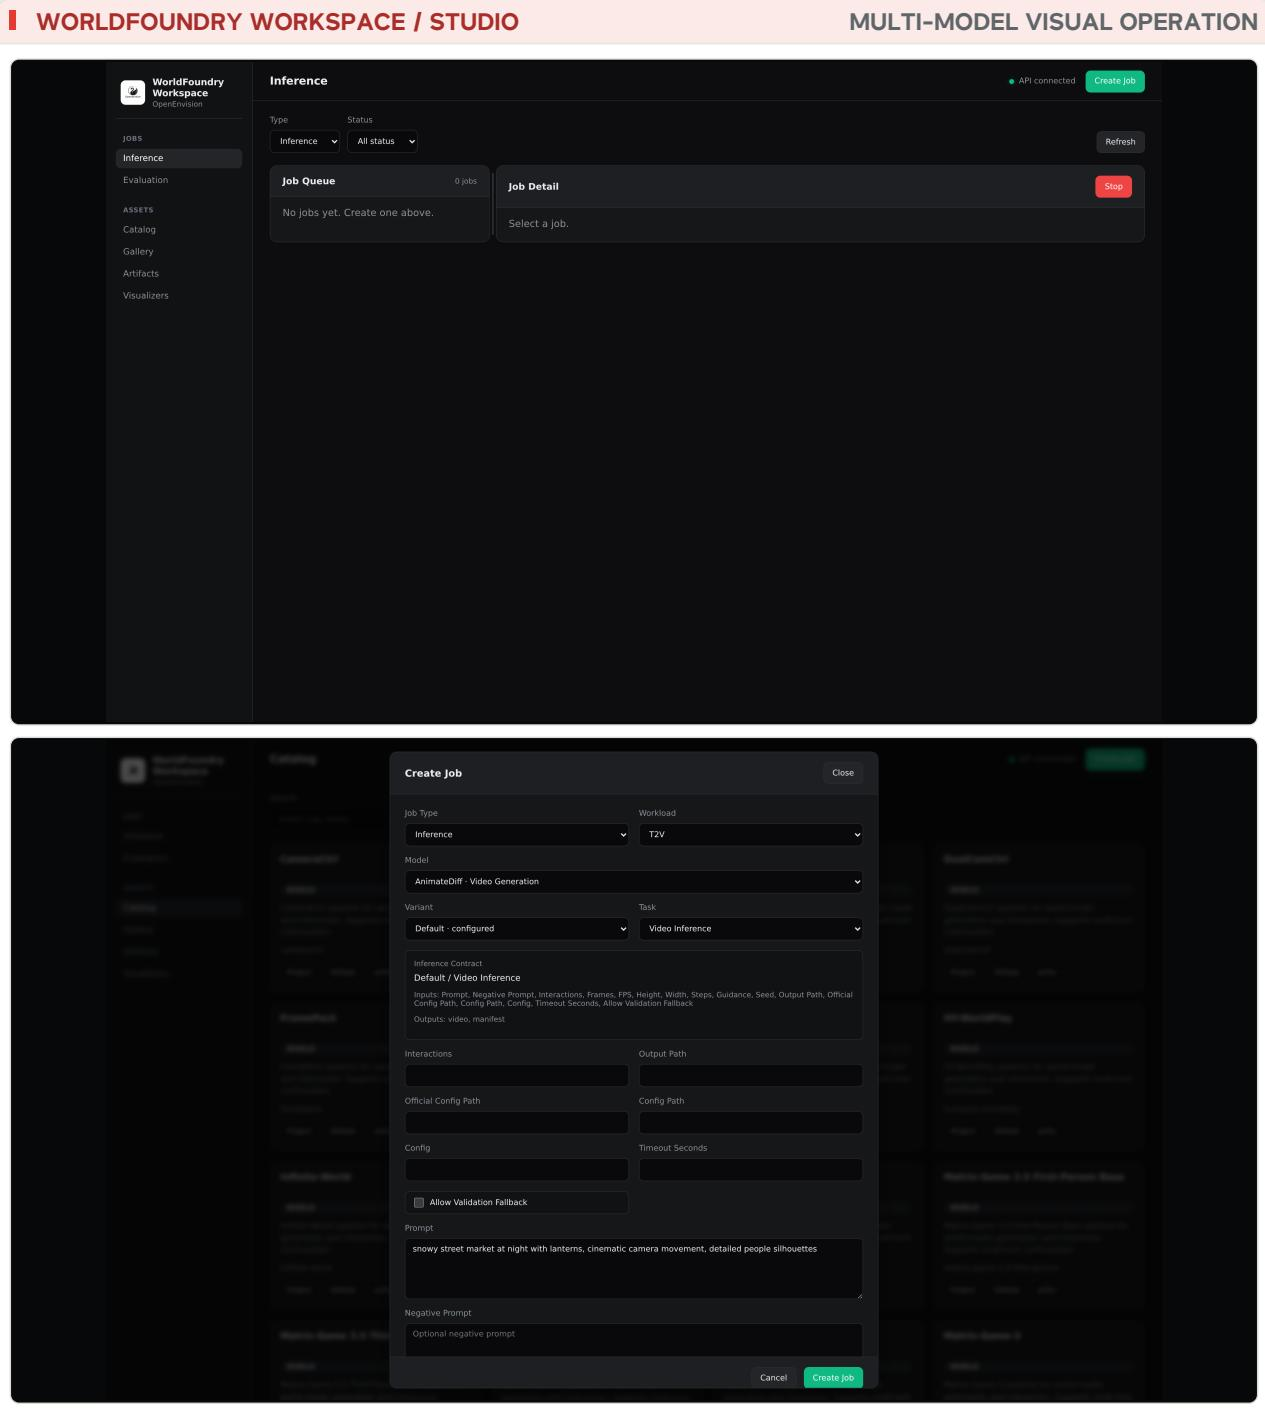
The browser based Workspace supports multi model job configuration, model specific input specification, runtime selection, execution monitoring, artifact inspection, and cross run comparison, while the single model Studio offers tailored controls for interactive use and detailed inspection. Studio additionally provides modality aware visualization and interaction, displaying generated videos, rendering point clouds and meshes, and presenting Gaussian splats.
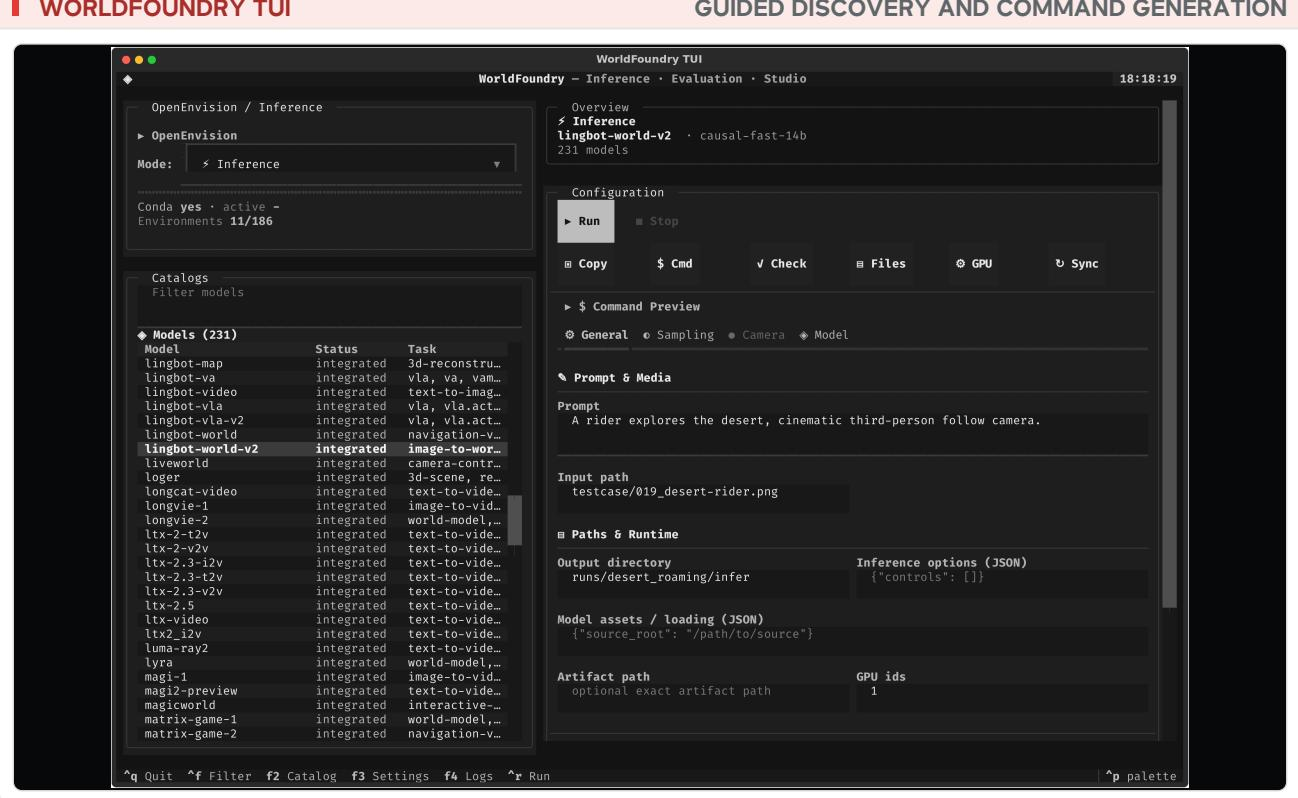
The terminal user interface guides discovery by querying model and benchmark catalogs, checking requirements and readiness, and resolving an executable command before resources are allocated.
Unified Inference and Interaction resolves requests through a manifest driven execution sequence. Each model identifier is mapped to a canonical catalog entry specifying provenance, supported tasks, input and output modalities, required assets, and runtime configuration. The input is encoded as a GenerationRequest, which defines common fields for sample identity, task context, conditioning inputs, control signals, and output specifications while retaining model specific payloads. The WorldModelRunner coordinates execution through two complementary abstractions: an Operator and a Pipeline. The Operator handles task specific adaptation, including input validation, preprocessing, translation into model native arguments, and postprocessing. The Pipeline manages the model lifecycle and inference runtime, including model construction, checkpoint loading, device placement, and distributed execution.
Artifact and Representation Contracts define a two level contract system that separates sample level execution from run level organization. A GenerationRequest represents a single execution unit, while the corresponding GenerationResult records stable sample and model identifiers, execution status, errors, timing, and output references. Each materialized output is described by an ArtifactRef, which identifies externally stored content by its semantic role and URI. At the run level, files such as execution_plan.json, requests.jsonl, results.jsonl, and run_manifest.json track per stage status, materialized outputs, and resolved run identity. This persistent record structure decouples artifact inspection and evaluation from model execution.
Evaluation and Evidence treats evaluation as an artifact centered process, allowing scoring to proceed independently of the originating model runtime once outputs are materialized. The evaluation pipeline resolves the model, benchmark, metrics, data source, and runtime profile. Metrics compute per sample measurements and aggregate statistics, whereas benchmarks prescribe data, sample coverage, preprocessing, and aggregation rules. The evidence layer records evaluation outcomes and the conditions under which they support scientific comparisons, producing a scorecard.json that serves as the authoritative machine readable record of score validity, provenance, and protocol fidelity.
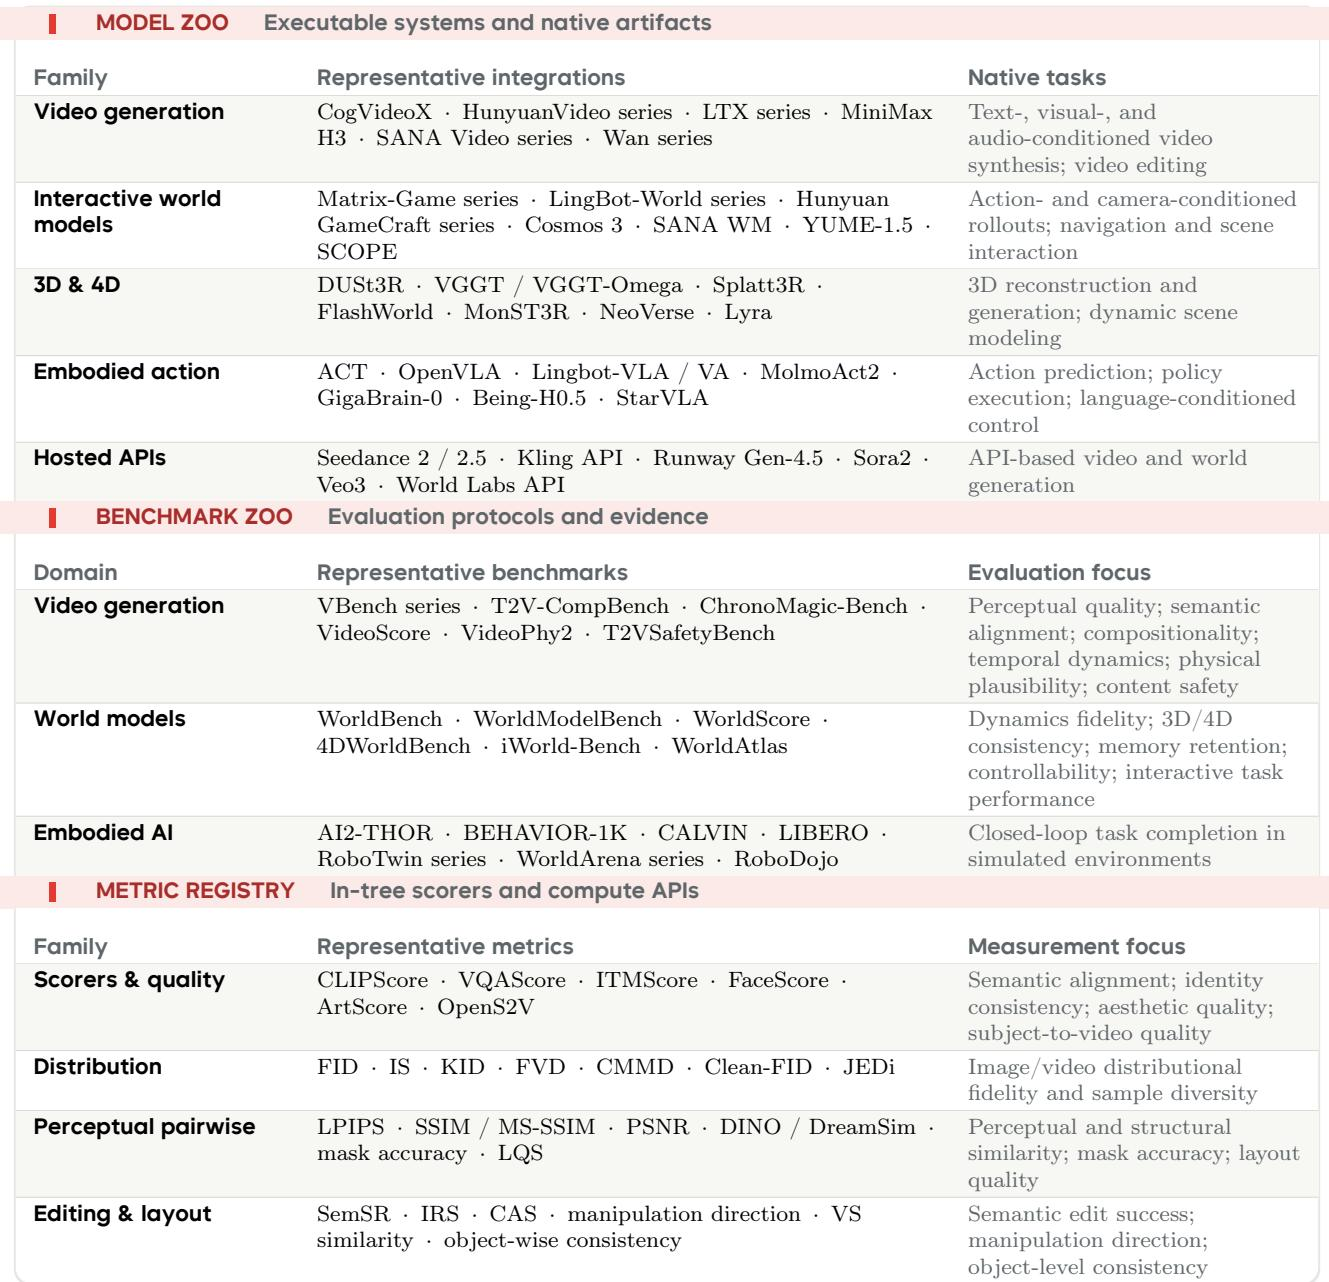
The Model and Benchmark Zoo maintains manifest driven registries linking model and benchmark discovery to explicit, auditable integration states. Entries are categorized by operational requirements, such as video models, generative world models, 3D and 4D models, and embodied prediction models. Each entry documents official sources, licensing, tasks, checkpoint references, and runtime bindings. Catalog inclusion establishes discoverability, while source availability, implementation status, asset readiness, and execution evidence are tracked independently to distinguish structural conformance from complete benchmark reproduction.
Experiment
The empirical validation evaluates WorldFoundry on 128 NVIDIA A100/H100 GPUs across four model families: video generation, interactive world modeling, 3D/4D generation, and embodied action generation. It assesses whether the framework preserves native input and output semantics, provides consistent behavior across CLI, Python API, and web interfaces, and produces traceable evidence for reported results. Qualitative findings indicate that video models improve visual fidelity and conditioning but still face event-level consistency challenges; interactive world models must separate scene appearance recall from persistent action-dependent state changes; 3D/4D methods need to distinguish observed reconstruction from plausible spatial completion and temporal correspondence. For embodied action, closed-loop task completion and recovery under comparable data, embodiment, and latency constraints matter more than offline action accuracy or predicted visual quality alone.
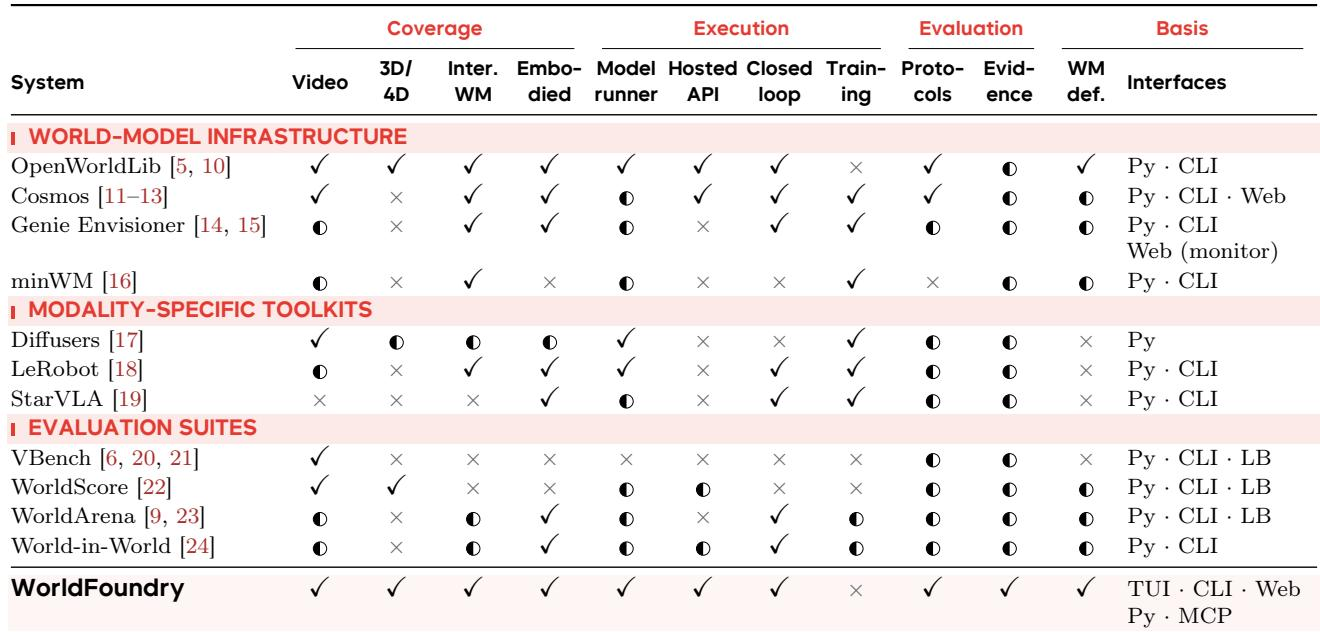
World-model infrastructures differ mainly in execution, closed-loop readiness, and interface breadth. OpenWorldLib is the only listed system with documented execution and training workflows, while Cosmos offers broader interfaces and model-runner support but lacks execution. Genie Envisioner and minWM are more constrained, and no entry marks closed loop as fully supported. OpenWorldLib is the only compared system with documented execution and training workflows, but it lacks model-runner support. No compared infrastructure marks closed loop as fully supported; the available entries mark it as specialized or constrained. Cosmos provides the widest interface support and includes model-runner support, while Genie Envisioner and minWM lack execution and interactive world-model support.
The catalog spans video generation, interactive world models, 3D and 4D modeling, embodied action policies, and hosted APIs, with representative integrations in each area. Evaluation combines offline action prediction with closed-loop execution in compatible manipulation environments such as LIBERO and RoboTwin, measuring task completion, instruction adherence, control accuracy, trajectory smoothness, execution latency, and recovery. Published findings suggest that world modeling is most useful when it supports executable actions and timely correction, making closed-loop completion the central evidence. Embodied action coverage includes representatives such as ACT, OpenVLA, Lingbot-VLA / VA, MolmoAct2, GigaBrain-0, Being-H0.5, and StarVLA. Closed-loop evaluation is emphasized over offline action accuracy; in one LIBERO-10 example, OpenVLA completes a single-object pick-and-place but reaches the step limit on multi-stage tasks. World-model contributions are distinguished by where prediction enters the control pipeline, including training-data augmentation, representation supervision, and online action generation.
The experiments compare world-model infrastructures and embodied action policies, finding that they differ mainly in execution, closed-loop readiness, and interface breadth: OpenWorldLib is the only system with documented execution and training workflows but lacks model-runner support, Cosmos offers the widest interfaces and model-runner support without execution, and no system fully supports closed-loop operation. Evaluation spans video generation, interactive world models, 3D and 4D modeling, and embodied policies, combining offline action prediction with closed-loop execution in LIBERO and RoboTwin. The main conclusion is that world modeling is most useful when it supports executable actions and timely correction, making closed-loop completion the central evidence rather than offline accuracy, as shown by OpenVLA completing only single-object pick-and-place but hitting step limits on multi-stage tasks. World-model contributions are further distinguished by whether prediction enters as training-data augmentation, representation supervision, or online action generation.