Command Palette
Search for a command to run...
BirdDreams: Joint Perspective and BEV Video Generation for a Plausible, Reactive Driving World Model
BirdDreams: Joint Perspective and BEV Video Generation for a Plausible, Reactive Driving World Model
Junyoung Seo Jaewoo Seo Seungryong Kim Laura Leal-Taixé Xiuming Zhang Seung Wook Kim
Abstract
Driving world models aim to simulate how a scene unfolds under diferent ego actions. This requires plausible motion of surrounding vehicles as well as precise ego-trajectory control. Learning vehicle motion from perspective video alone is challenging because motion is entangled with appearance and vehicles can be occluded. Prior work therefore conditions video generation on layouts that specify vehicle motion, providing control over surrounding vehicles but requiring their future trajectories as inputs. We introduce BirdDreams, an autoregressive driving world model that jointly generates perspective video and a schematic bird’s-eye-view (BEV) video, making scene layout part of the predicted future. The BEV, rendered from scene annotations for training, depicts roads and vehicles as simple shapes at a fixed metric scale, providing a top-down view of their positions and motion with reduced occlusion between vehicles. Perspective video, by contrast, retains scene details that the BEV omits, such as trafic signals and object appearance. Joint attention between two video difusion transformers, one per stream, lets each stream inform the other during generation. The predicted BEV also provides a geometric interface for ego control: we translate and rotate its latest frame along an input ego trajectory and use the resulting frames as a soft condition that shows how the scene would appear to move if only the ego vehicle moved. At inference, BirdDreams generates both videos from a single camera image without requiring an HD map or vehicle-state inputs. On PhysicalAI-AV and nuScenes, BirdDreams follows input ego trajectories more faithfully than prior driving world models and generates more plausible ego motion without ego-action conditioning. Human evaluation shows that BirdDreams outperforms a perspective-only baseline in generating realistic surrounding-vehicle behavior.
One-sentence Summary
Researchers from NVIDIA and KAIST introduce BirdDreams, an autoregressive driving world model that jointly generates perspective and bird’s-eye-view (BEV) video with joint attention between two video diffusion transformers, uses the predicted BEV as a geometric ego-control interface, and from a single camera image follows input ego trajectories more faithfully on PhysicalAI-AV and nuScenes without requiring an HD map or vehicle-state inputs.
Key Contributions
- BirdDreams is an autoregressive driving world model that jointly predicts perspective video and a schematic bird's-eye-view (BEV) video, making scene layout part of the predicted future rather than an external input. The BEV stream represents roads and vehicles as simple shapes at a fixed metric scale, while joint attention between two video diffusion transformers lets the perspective and BEV streams inform each other.
- The predicted BEV provides a geometric control interface: its latest frame is translated and rotated along an input ego trajectory and the resulting frames are used as a soft condition. At inference, BirdDreams generates both videos from a single camera image without requiring an HD map or vehicle-state inputs.
- On PhysicalAI-AV and nuScenes, BirdDreams achieves lower ego-trajectory errors than prior driving world models with and without ego-action conditioning. Human evaluation shows that BirdDreams generates more realistic surrounding-vehicle behavior than a perspective-only baseline.
Introduction
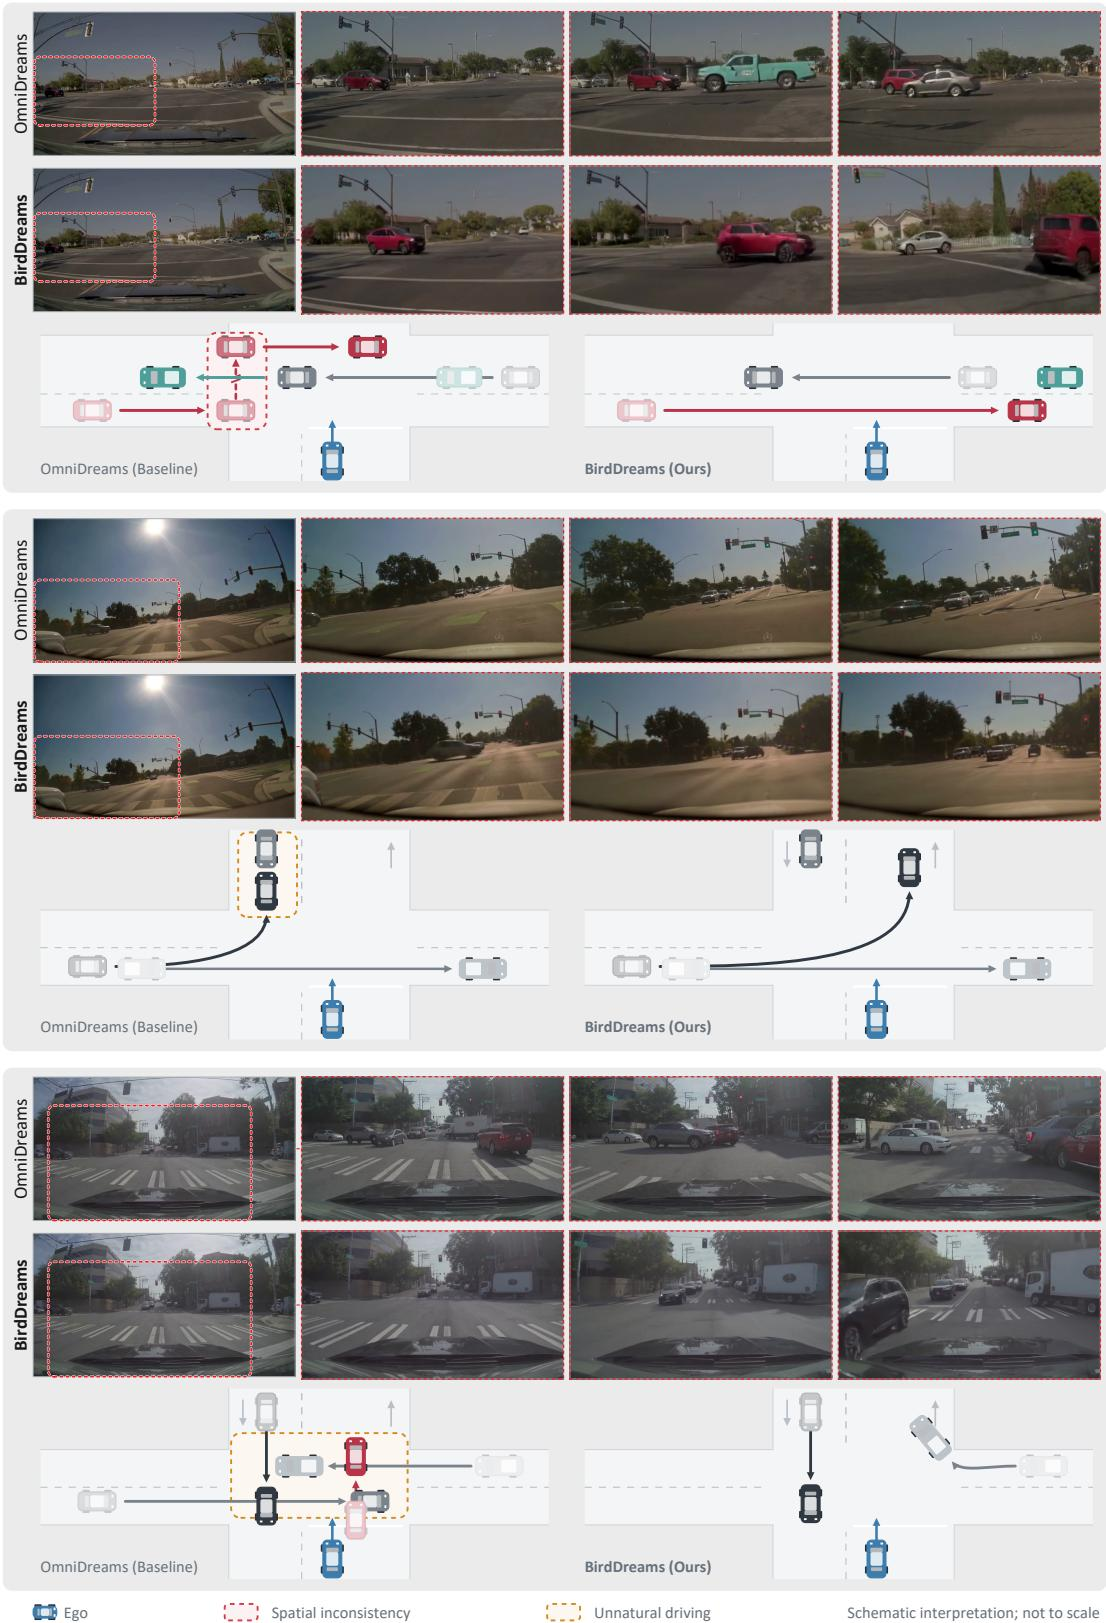
Simulation lets autonomous driving systems be tested in rare, dangerous scenarios that are hard to reproduce safely on real roads. Driving world models learn from real driving videos to synthesize future observations conditioned on ego actions, but surrounding vehicles must respond plausibly to changed ego maneuvers. Prior models such as OmniDreams condition generation on external scene layouts; when those layouts come from logged trajectories, surrounding vehicles are fixed to recorded motion and cannot react to a new ego maneuver, while models without layout inputs struggle because perspective motion is entangled with texture, lighting, occlusion, and camera distance. The authors introduce BirdDreams, an autoregressive driving world model that jointly generates perspective video and schematic bird’s-eye-view video, making scene layout part of the predicted future. The BEV stream provides a fixed metric scale, top-down view, and simplified semantic scene representation for vehicle motion, while joint attention couples it with photorealistic perspective video; the predicted BEV also serves as an action interface via reprojection along the ego trajectory to improve trajectory following.
Dataset
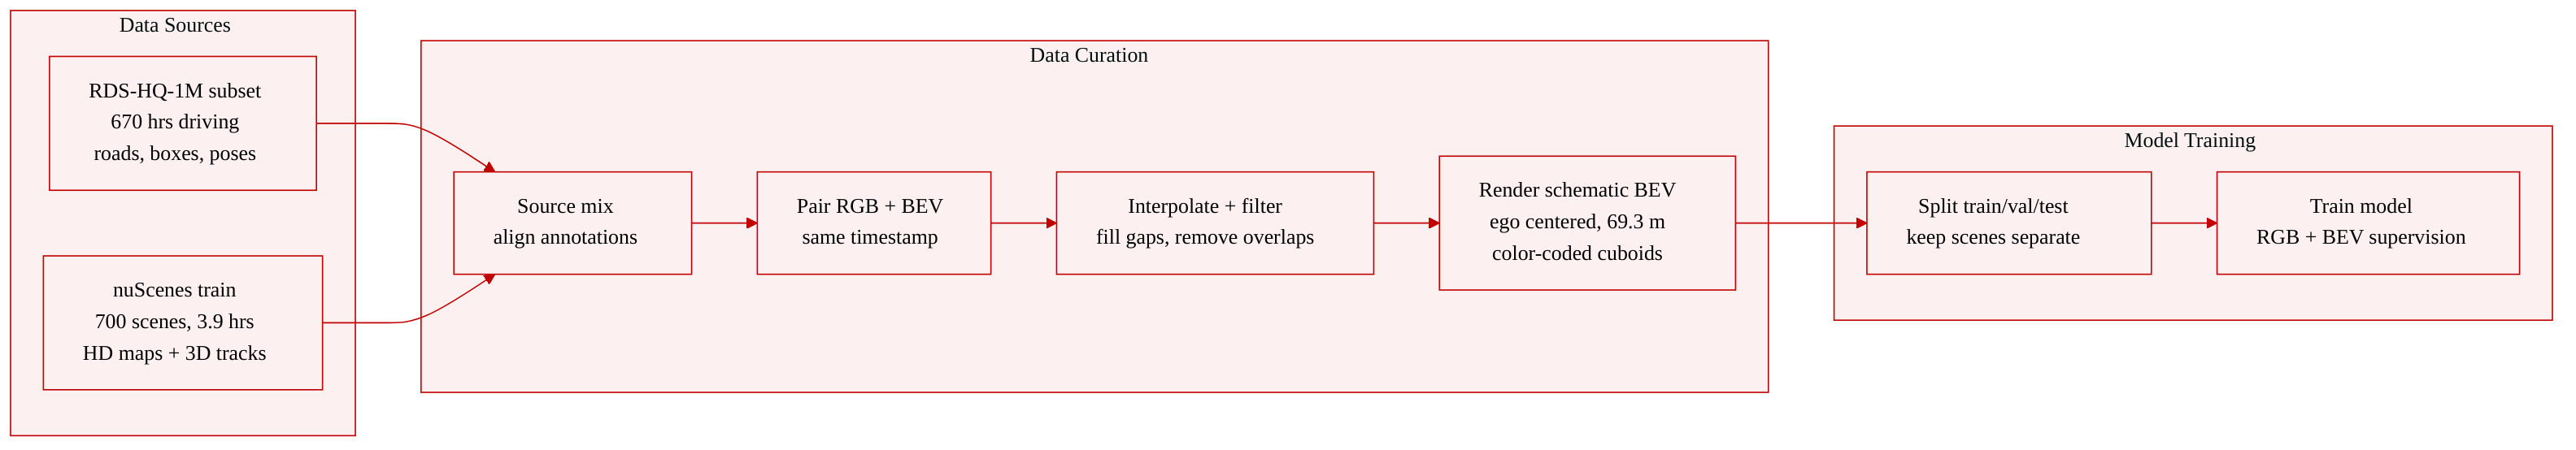
The authors construct paired training examples from front-camera RGB video and a rendered schematic bird’s-eye-view (BEV) video of the same scene.
-
Sources and scale: The data combines a subset of RDS-HQ-1M with about 670 hours of driving and the official nuScenes training split with 700 scenes and about 3.9 hours. The RDS-HQ-1M subset provides road-layout annotations, tracked object boxes, ego poses, and camera calibration. Road geometry is built from lanes, road boundaries, crosswalks, and wait lines. For nuScenes, the authors use HD vector maps and annotated 3D box tracks.
-
Pair construction: Each RGB frame is paired with a BEV frame rendered from object positions and orientations at the same capture time.
-
Track interpolation and filtering: Object boxes may be annotated less frequently than RGB frames. The authors use track IDs to interpolate the position and orientation of the same object between earlier and later annotations, including during temporary occlusions. Duplicate or excessively overlapping vehicle boxes are removed before rendering.
-
BEV rendering: BEV frames are rendered in orthographic overhead view with the ego vehicle centered and facing upward. Road elements are drawn as polylines and polygons, and objects as oriented cuboids. Each frame covers a square of roughly 69.3 m per side in both datasets, so pixel displacement maps consistently to physical distance across scenes. This pixel-to-meter mapping is also used for ego-action reprojection.
-
Visual schema: Road boundaries are magenta, crosswalks purple, and pedestrians yellow. Vehicle cuboids are shaded red at the front and blue at the rear to expose heading. The BEV representation preserves object positions and headings relative to the road while removing texture and perspective.
-
Model usage: The paired RGB and BEV videos are used as training data. The BEV video provides explicit supervision for vehicle motion relative to the road, complementing appearance and motion supervision from the RGB video.
Method
The authors introduce BirdDreams, a driving world model that jointly predicts photorealistic perspective videos and schematic bird's eye view (BEV) videos to capture scene dynamics and vehicle responses under ego actions. Given an initial perspective RGB image I0 and optional ego actions A0:T, the model generates the joint conditional distribution pϕ(I1:T,B0:T∣I0,c). By removing texture and lighting variations from the BEV prediction target, the architecture focuses learning on road relative vehicle motion while allowing the perspective branch to leverage explicit scene dynamics.
Refer to the framework diagram:
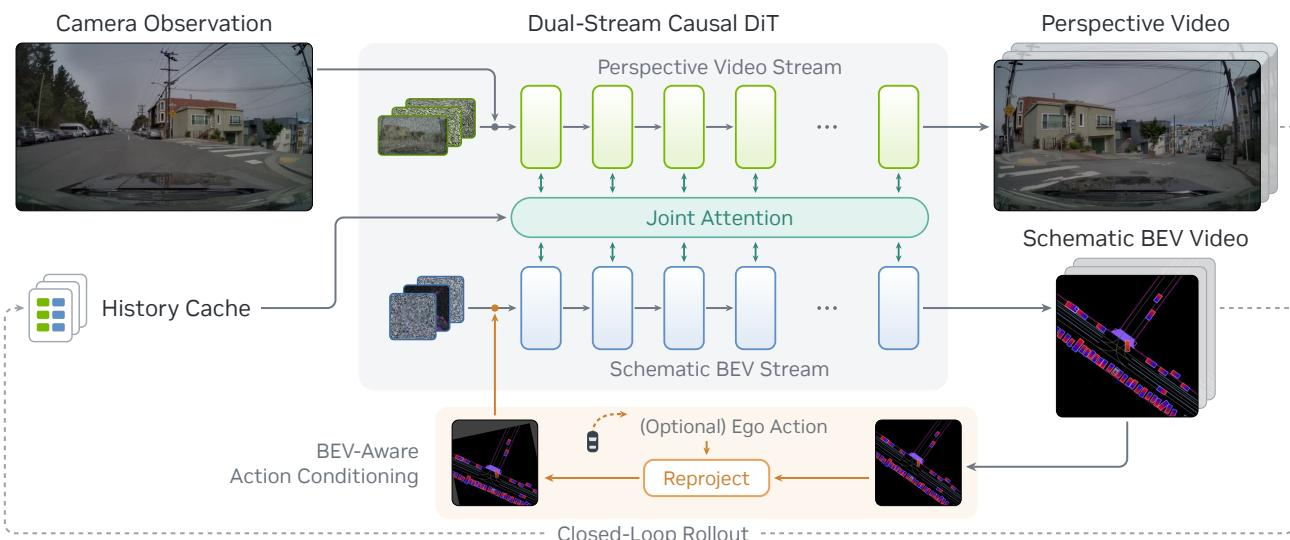
The core architecture is a dual stream causal mixture of transformers. The perspective branch inherits a pretrained OmniDreams backbone, while the BEV branch is initialized with a copy of its weights. A frozen video VAE encodes each stream into latents, which are partitioned into chunks of three latent frames. Attention is bidirectional within each chunk and causal across chunks. At every transformer block, joint attention allows queries from each branch to attend to keys and values from both streams, enabling the exchange of metric scene dynamics and visual details while retaining separate projections and output heads for specialization.
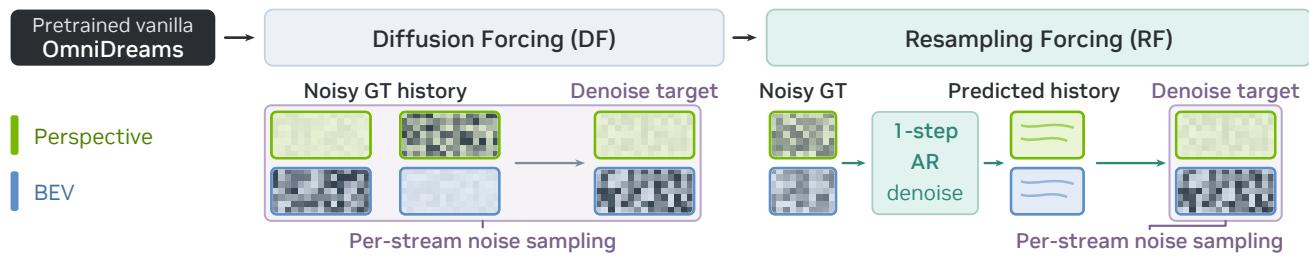
To train this joint generation, the authors employ Diffusion Forcing with per stream noise sampling. Noise levels are sampled independently for the perspective and BEV streams within each chunk. Clean VAE latents zks are corrupted via rectified flow interpolation:
xks=(1−σks)zks+σksϵks,ϵks∼N(0,I)where σks is shared across the three latent frames in a chunk but sampled independently across chunks and streams. The model predicts the flow velocity with a joint flow matching loss that averages the squared error over latent elements and chunks, weighting both streams equally to prevent the larger perspective frames from dominating.
As shown in the figure below:
For ego action conditioning, the model leverages the fixed metric scale of the BEV. The latest predicted BEV frame Br is reprojected to the target ego pose (pt,θt) to account for ego induced apparent motion. The reprojection maps each target pixel u back to the reference frame:
Bt(u)=Br(Π[R(θr)T(R(θt)Π−1(u)+pt−pr)])These reprojected frames are VAE encoded, slightly noised, and added to the BEV input tokens via a zero initialized projection. Joint attention then conveys this condition to the perspective branch.
During inference, the model performs a causal rollout, generating latents chunk by chunk while caching keys and values from previous chunks. To improve robustness during autoregressive generation, the authors fine tune the model with Resampling Forcing. This process corrupts ground truth chunks at a shared noise level τ and constructs the conditioning history autoregressively by denoising each chunk with a single Euler step:
zk=sg[xk(τ)−τvϕ(xk(τ),z<k,τ)]Target denoising then proceeds with independently sampled noise levels across chunks and streams.
The per stream training also enables flexible conditioning at inference. The model can generate synchronized videos when a full video is provided in one stream, or it can generate both perspective and BEV videos from just an initial frame of either modality.
As shown in the figure below:
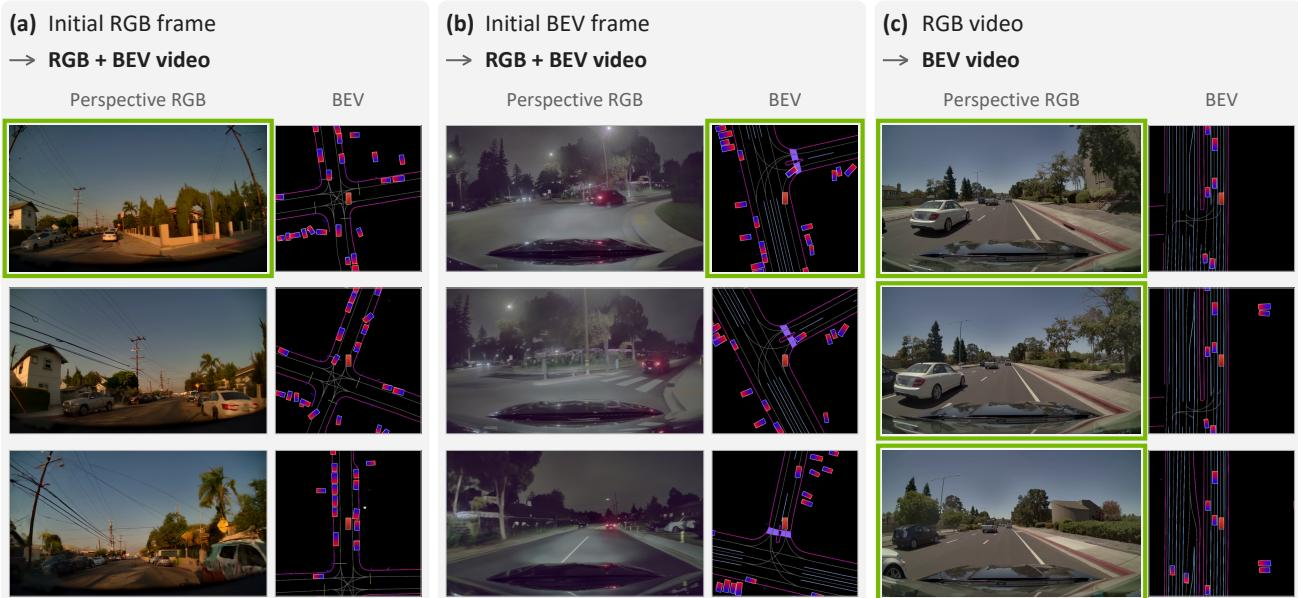
Furthermore, the schematic top view facilitates scenario editing. Users can customize driving scenarios by adding vehicles or adjusting their positions and headings directly in the projected BEV layout. The model then jointly generates the corresponding perspective and BEV videos from this edited initial layout, synthesizing scene appearance and subsequent vehicle motion without requiring a corresponding perspective image.
As shown in the figure below:
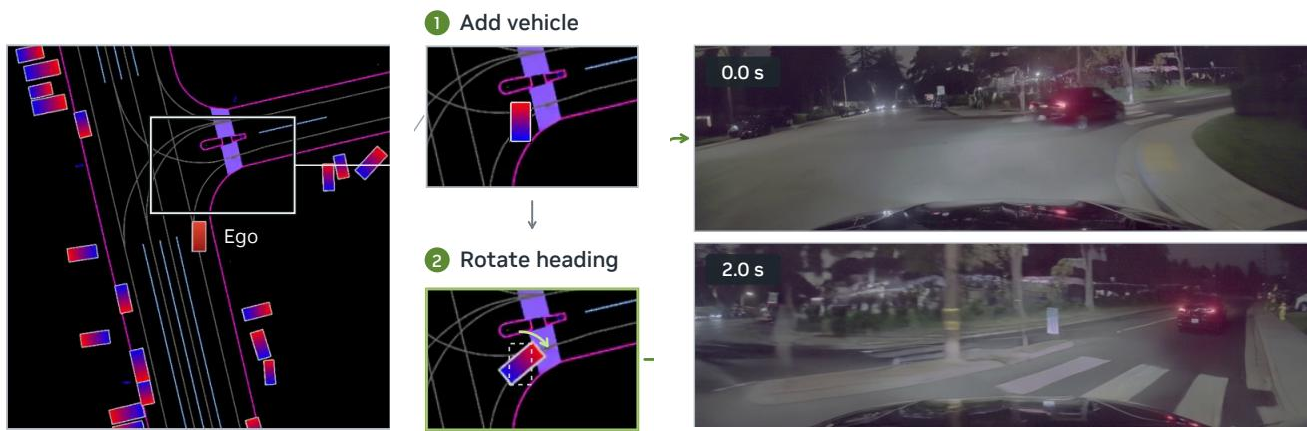
Experiment
The experiments evaluate BirdDreams on PhysicalAI-AV and nuScenes for perspective video generation and ego-trajectory control, both with and without ego-action conditioning, and compare it with open driving world models. Results show that BirdDreams generates more accurate ego motion and higher-quality video, while counterfactual rollouts and human evaluation indicate more realistic surrounding-vehicle reactions than baselines. Additional analyses validate that independent per-stream noise sampling improves generation quality, that joint perspective-BEV modeling offers a small benefit for ego-trajectory prediction, and that BEV editing supports controllable scenario generation.
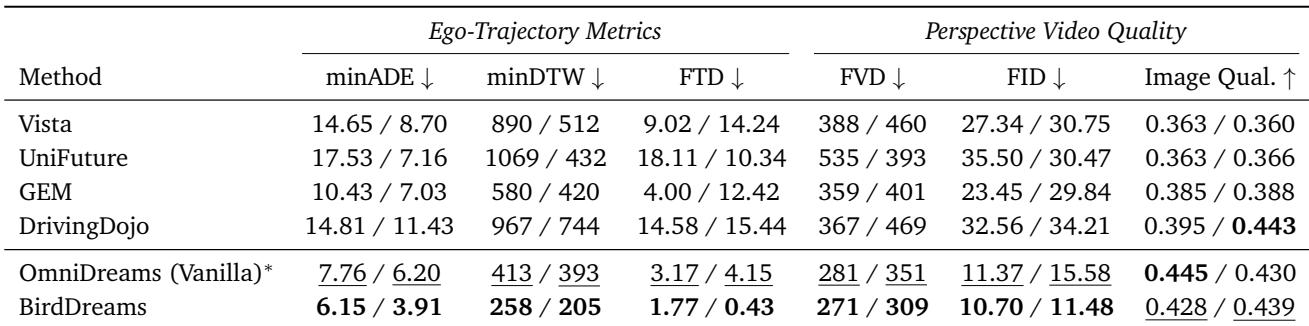
BirdDreams achieves the best ego-trajectory and video quality results among the compared methods when no ego-action conditioning is provided, including the lowest minADE, minDTW, FTD, FVD, and FID on both PhysicalAI-AV and nuScenes. Its frame-level image quality is not the best, ranking second on both benchmarks behind OmniDreams (Vanilla) on PhysicalAI-AV and DrivingDojo on nuScenes. The relative minADE improvement over OmniDreams (Vanilla) is larger on nuScenes than on PhysicalAI-AV. BirdDreams has the lowest ego-trajectory errors and the lowest FTD, FVD, and FID among all evaluated methods on both benchmarks. BirdDreams ranks second in image quality on both datasets, behind OmniDreams (Vanilla) on PhysicalAI-AV and behind DrivingDojo on nuScenes. The minADE improvement over OmniDreams (Vanilla) is larger on nuScenes than on PhysicalAI-AV.
With ego-action conditioning, BirdDreams executes the provided ego trajectory more faithfully than the compared driving world models on both PhysicalAI-AV and nuScenes, attaining the lowest trajectory error metrics. It also achieves the best perspective video fidelity metrics and ranks first for per-frame image quality on PhysicalAI-AV and second on nuScenes. The strongest baseline, OmniDreams (Plücker), uses Plücker ray embeddings for ego-motion conditioning. BirdDreams records the lowest ADE, DTW, and FTD among evaluated methods on both benchmarks. Relative to OmniDreams (Plücker), BirdDreams reduces ADE by 35% on PhysicalAI-AV and 36% on nuScenes. BirdDreams also achieves the best FVD and FID, while its image quality ranks first on PhysicalAI-AV and second on nuScenes.
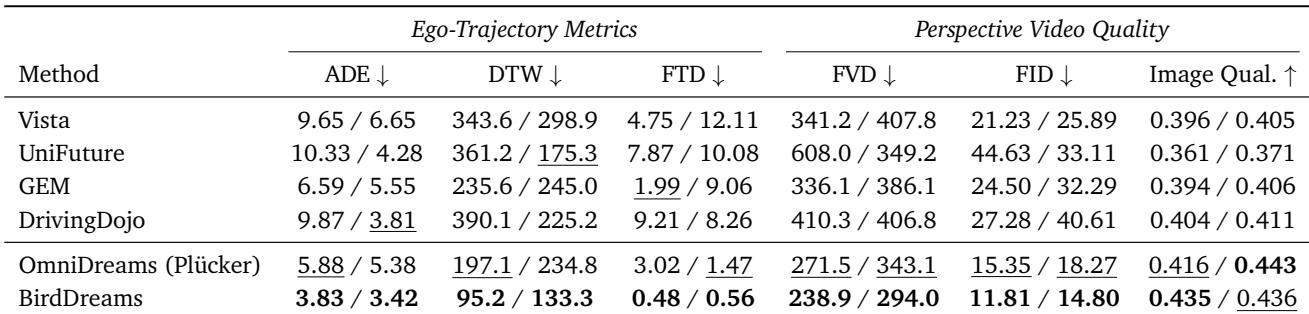
The first experiment evaluates unconditional generation quality for ego trajectories and visual fidelity on PhysicalAI-AV and nuScenes, where BirdDreams achieves the strongest overall trajectory and video quality while frame-level image quality ranks second. The second experiment adds ego-action conditioning to validate trajectory following and conditioned visual generation, showing that BirdDreams executes the provided ego trajectory more faithfully than baselines and delivers the best video fidelity, with image quality first on PhysicalAI-AV and second on nuScenes. Across both settings, BirdDreams consistently outperforms the strongest baseline, OmniDreams, with notably larger trajectory improvements under conditioning.