HyperAI
Command Palette
Search for a command to run...
Papers
Daily updated cutting-edge AI research papers to help you keep up with the latest AI trends
papers
Scaling Code-Assisted Chain-of-Thoughts and Instructions for Model Reasoning
CoDA: Coding LM via Diffusion Adaptation
Fast-dLLM v2: Efficient Block-Diffusion LLM
Less is More: Recursive Reasoning with Tiny Networks
Fathom-DeepResearch: Unlocking Long Horizon Information Retrieval and Synthesis for SLMs
TaTToo: Tool-Grounded Thinking PRM for Test-Time Scaling in Tabular Reasoning
Hybrid Architectures for Language Models: Systematic Analysis and Design Insights
MITS: Enhanced Tree Search Reasoning for LLMs via Pointwise Mutual Information
Imperceptible Jailbreaking against Large Language Models
VChain: Chain-of-Visual-Thought for Reasoning in Video Generation
Video-LMM Post-Training: A Deep Dive into Video Reasoning with Large Multimodal Models
Paper2Video: Automatic Video Generation from Scientific Papers
Bridging the Gap Between Promise and Performance for Microscaling FP4 Quantization
Self-Improvement in Multimodal Large Language Models: A Survey
Compose Your Policies! Improving Diffusion-based or Flow-based Robot Policies via Test-time Distribution-level Composition
Large Reasoning Models Learn Better Alignment from Flawed Thinking
Efficient Multi-modal Large Language Models via Progressive Consistency Distillation
Apriel-1.5-15b-Thinker
StockBench: Can LLM Agents Trade Stocks Profitably In Real-world Markets?
Interactive Training: Feedback-Driven Neural Network Optimization
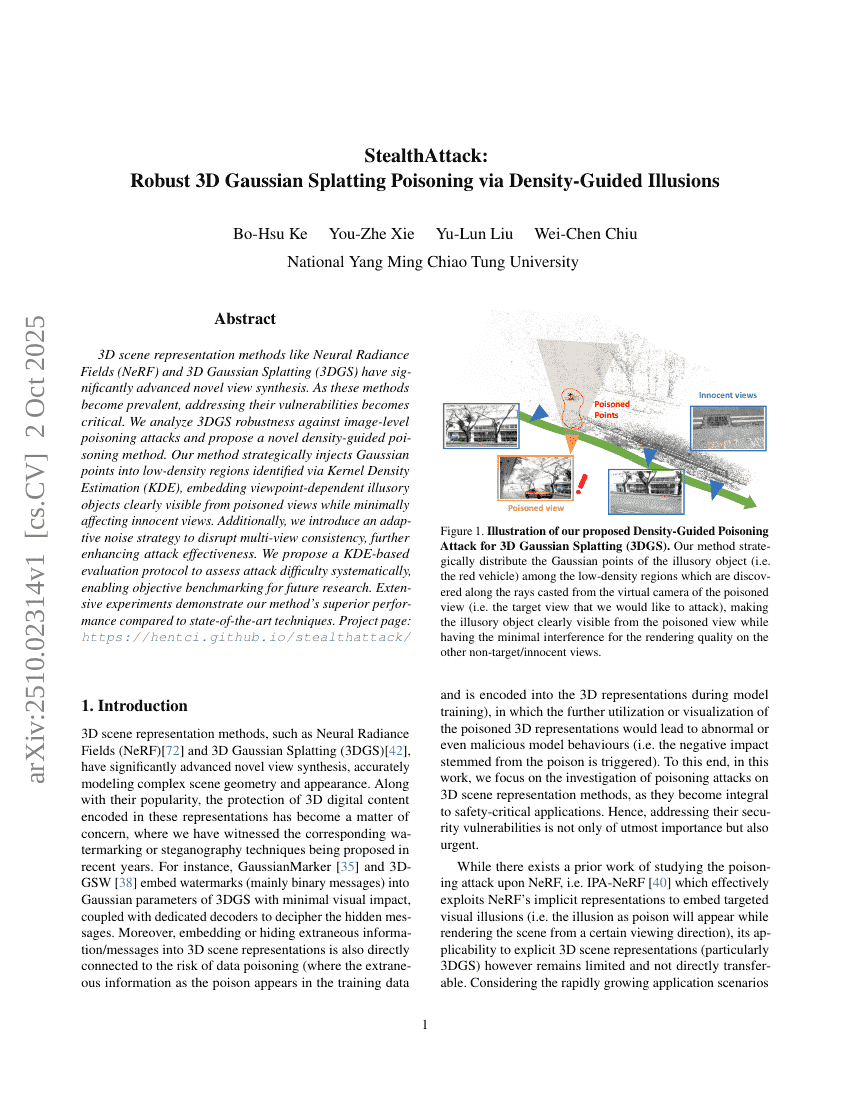
StealthAttack: Robust 3D Gaussian Splatting Poisoning via Density-Guided Illusions
ExGRPO: Learning to Reason from Experience
Self-Forcing++: Towards Minute-Scale High-Quality Video Generation
LongCodeZip: Compress Long Context for Code Language Models
PIPer: On-Device Environment Setup via Online Reinforcement Learning
Rethinking Reward Models for Multi-Domain Test-Time Scaling
Knapsack RL: Unlocking Exploration of LLMs via Optimizing Budget Allocation
GEM: A Gym for Agentic LLMs
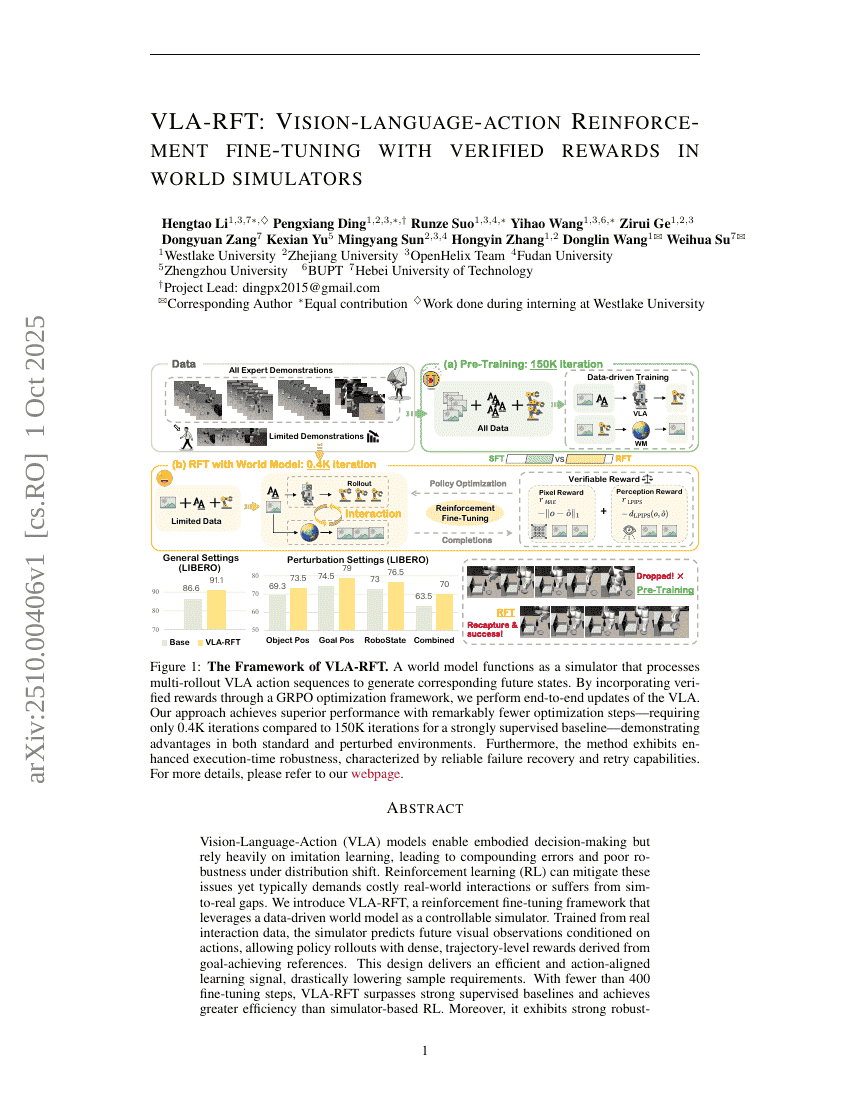
VLA-RFT: Vision-Language-Action Reinforcement Fine-tuning with Verified Rewards in World Simulators
DeepSearch: Overcome the Bottleneck of Reinforcement Learning with Verifiable Rewards via Monte Carlo Tree Search