Command Palette
Search for a command to run...
Download Meta's Largest Video Segmentation Dataset in One Click! Contains 50.9K real-world Videos, Covering 47 Countries
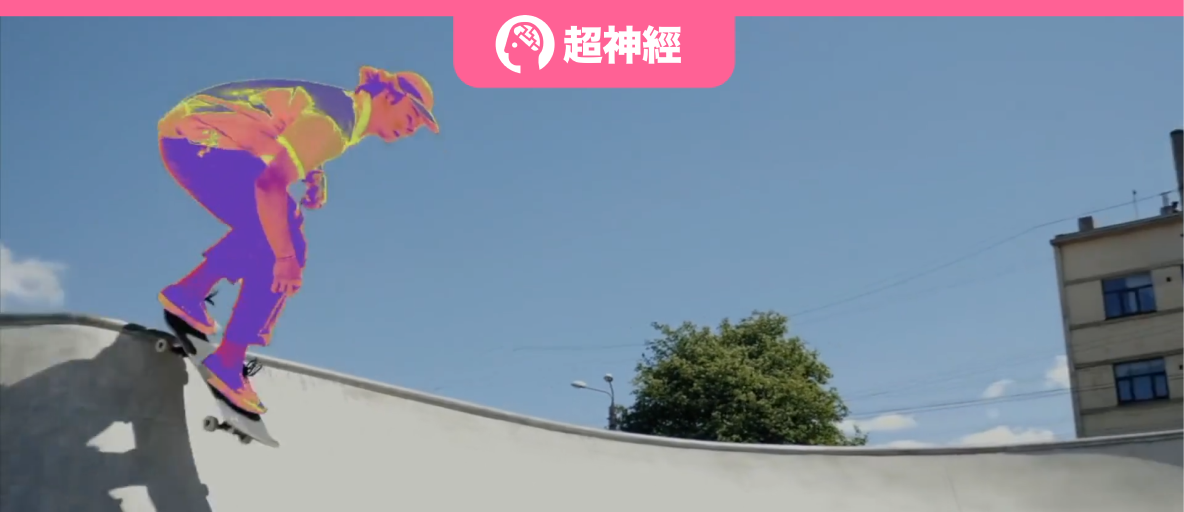
In April 2023, Meta released Segment Anything Model (SAM), claiming to be able to "segment everything". This innovative achievement that subverts traditional computer vision (CV) tasks has aroused widespread discussion in the industry and has been quickly applied to research in vertical fields such as medical image segmentation. Recently, SAM has been upgraded again.Meta open-sourced Segment Anything Model 2 (SAM 2), marking another epoch-making milestone in the field of computer vision.
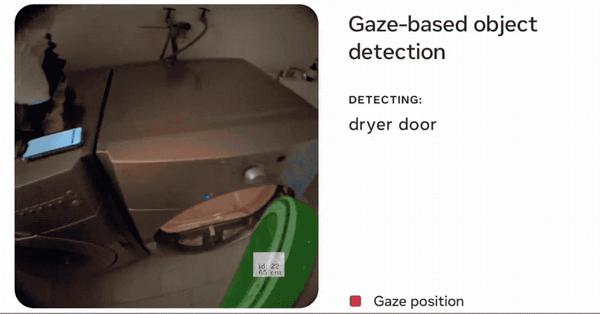
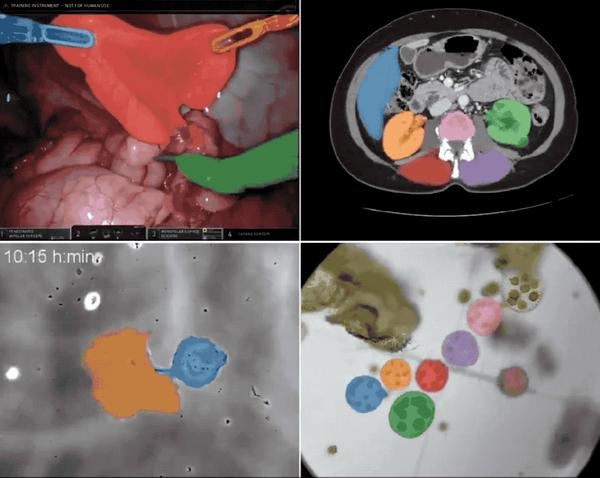
From image segmentation to video segmentation,**SAM 2 demonstrates superior performance in real-time cue segmentation.**The model introduces the segmentation and tracking functions of images and videos into a unified model. It can accurately identify and segment any object in an image or video by simply inputting a prompt (click, box or mask) on the video frame. This unique zero-sample learning capability gives SAM 2 extremely high versatility.It shows great application potential in the fields of medicine, remote sensing, autonomous driving, robotics, camouflaged object detection, etc. Meta is confident: "We believe that our data, models, and insights will become an important milestone in video segmentation and related perception tasks!"
It is true. As soon as SAM 2 was launched, everyone couldn’t wait to use it, and the effect was unbelievable!
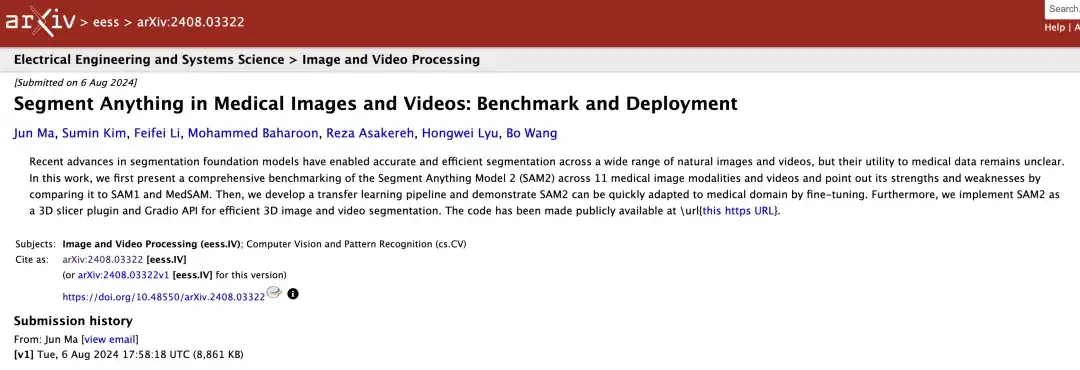
Original paper:
https://arxiv.org/abs/2408.03322
 SA-V video segmentation dataset direct download:
https://go.hyper.ai/e1Tth
More high-quality datasets to download: https://go.hyper.ai/P5Mtc
Beyond existing video segmentation datasets! SA-V covers multiple topics and multiple scenes
Meta researchers collected a large and diverse video segmentation dataset SA-V using Data Engine, as shown in the following table,**The dataset contains 50.9K videos, 642.6K masklets (191K manually annotated with the assistance of SAM 2, 452K automatically generated by SAM 2),**Compared with other common video object segmentation (VOS) datasets, SA-V has significantly improved the number of videos, masklets, and masks.**The number of annotated masks is 53 times that of any existing VOS dataset.**It provides a rich data resource for future computer vision work.
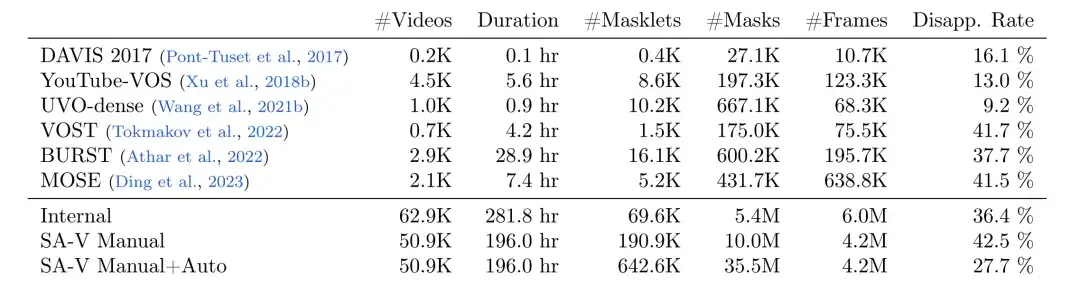
* SA-V Manual+Auto combines manually annotated labels with automatically generated mask segments
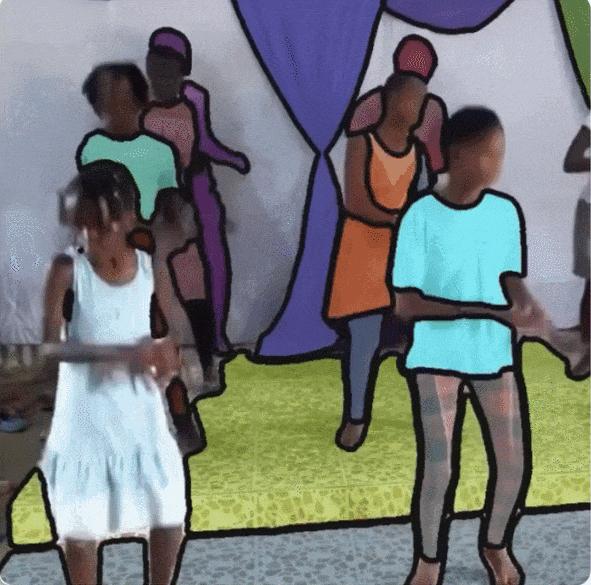
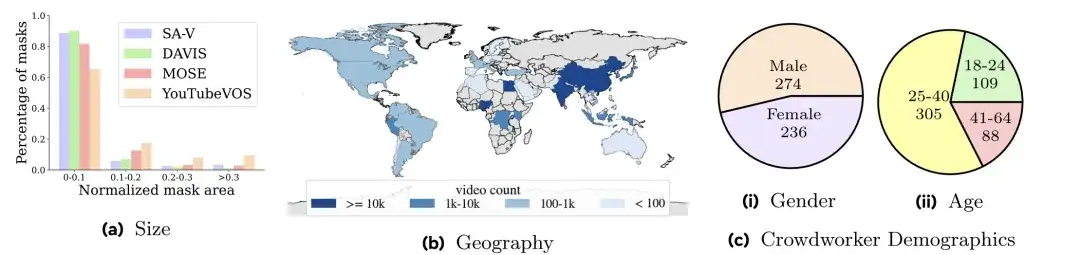
It is understood that the number of videos contained in SA-V exceeds the existing VOS dataset, and the average video resolution is 1401×1037 pixels.**The collected videos cover various daily scenes.**Including 54% of indoor scene videos and 46% of outdoor scene videos, with an average duration of 14 seconds. In addition,**The topics of these videos are also varied.**Including locations, objects, scenes, etc., Masks range from large objects (such as buildings) to fine-grained details (such as interior decoration).
SA-V video segmentation dataset direct download: https://go.hyper.ai/e1Tth
The above are the datasets recommended by HyperAI in this issue. If you see high-quality dataset resources, you are welcome to leave a message or submit an article to tell us!
More high-quality datasets to download:
https://go.hyper.ai/P5Mtc