HyperAI
Command Palette
Search for a command to run...
Papers
Daily updated cutting-edge AI research papers to help you keep up with the latest AI trends
papers
The Atention Triangle in Audio-Video Models
Bilevel Coordinated Reflection: A Game-Theoretic Approach to Multi-Agent LLM Systems
Dr. Claw: An AI Scientist Workspace for Vibe Research
WorldReward: Reward Modeling for Camera-Conditioned World Models
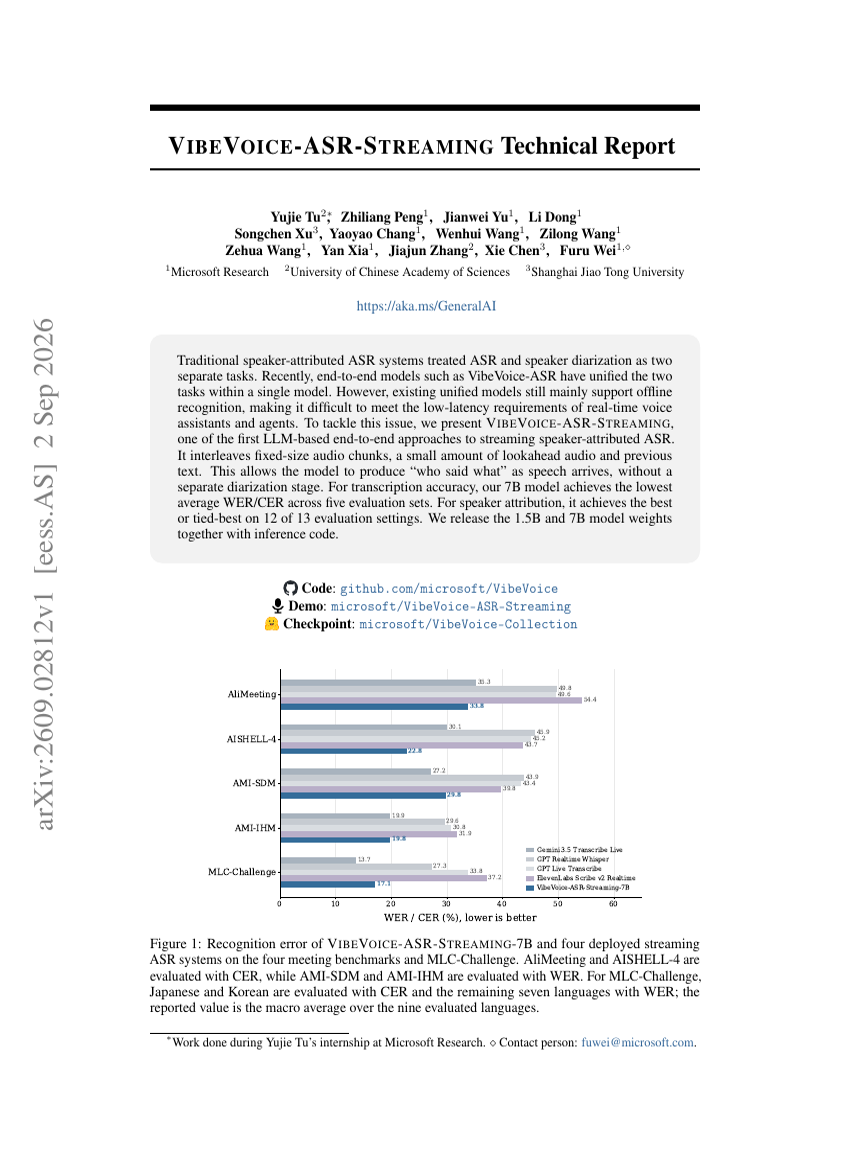
VIBEVOICE-ASR-STREAMING Technical Report
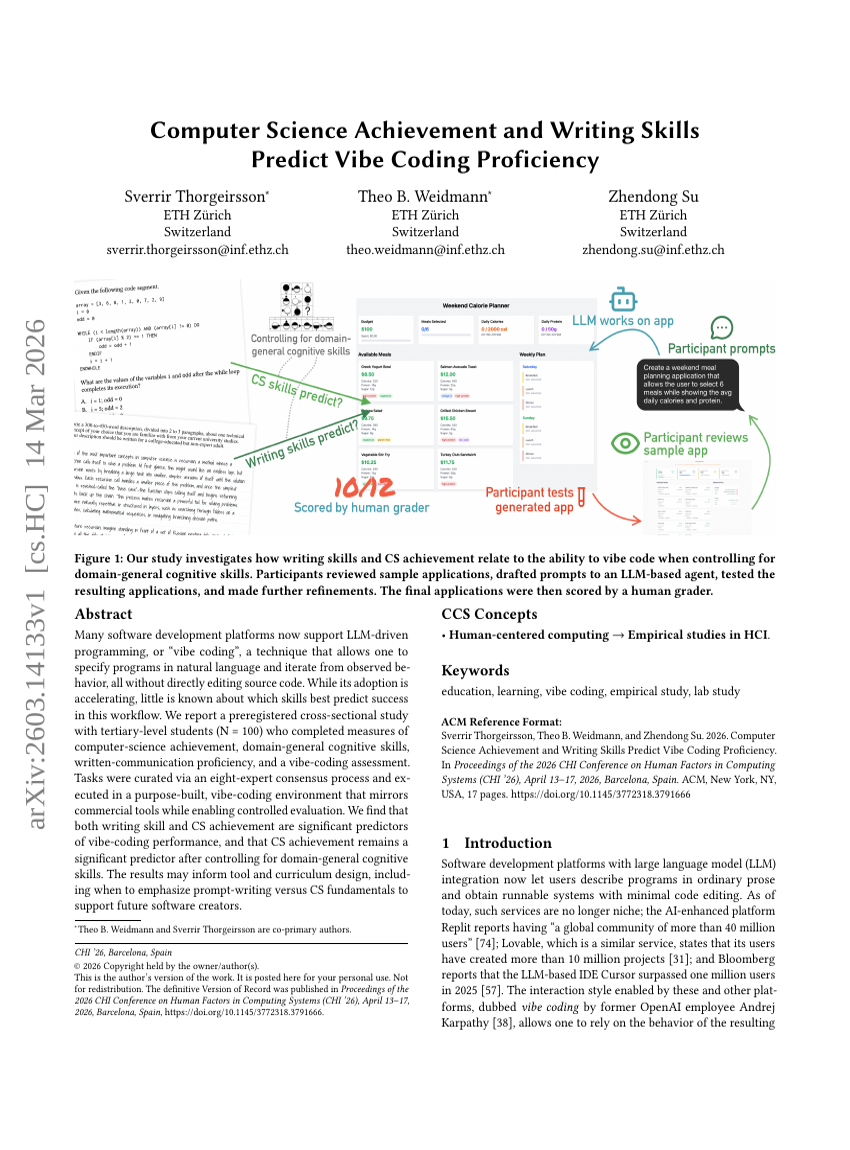
Computer Science Achievement and Writing Skills Predict Vibe Coding Proficiency
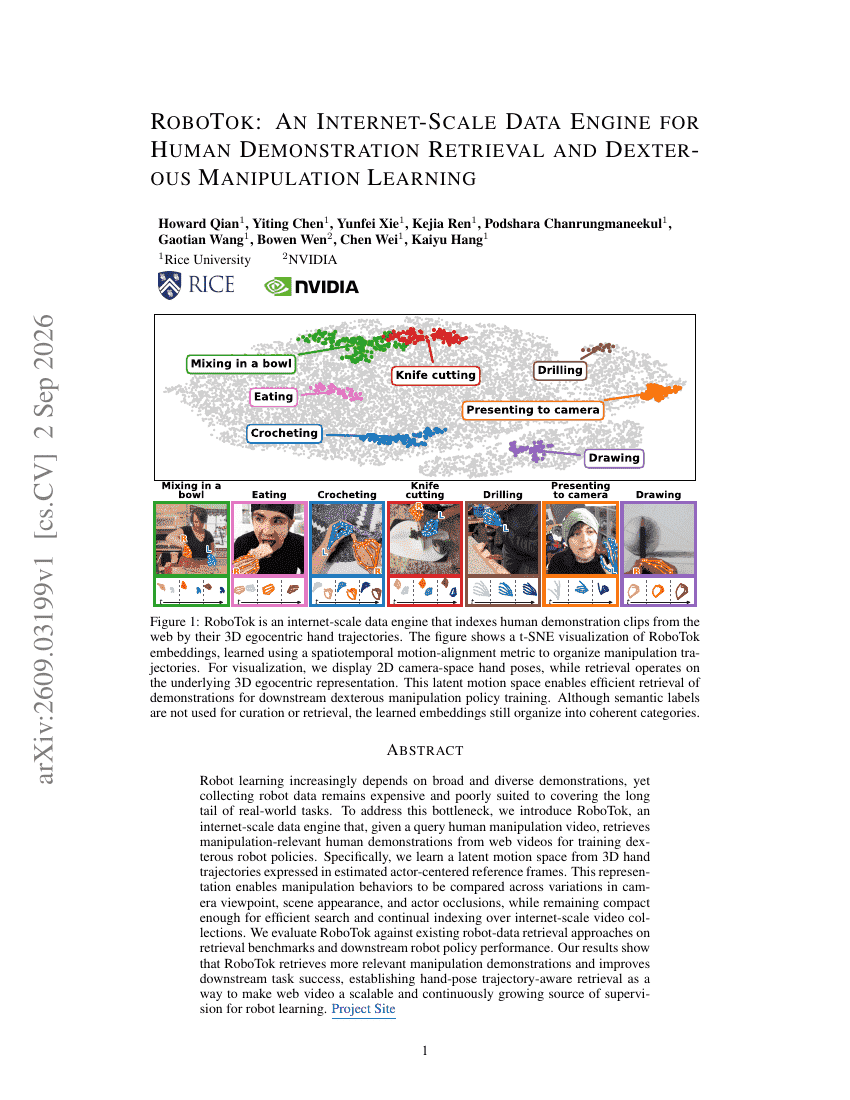
ROBOTOK: AN INTERNET-SCALE DATA ENGINE FOR HUMAN DEMONSTRATION RETRIEVAL AND DEXTEROUS MANIPULATION LEARNING
Knowing When Not to Reuse: Conditional Experience Transfer in Autonomous LLM Post-Training
Random Attention: Rethinking KV Cache Eviction for Eficient Reasoning
LLaDA-Image: Building Strong Image Generators with Fully Open Training Recipes
Terminal-Universe: Turning Agent Trajectories into Scalable Terminal Environments
Compile by Training: Turning Natural-Language Specifications into Local Neural Functions
HarnessDev: Can LLMs Create and Evolve Their Own Agent Harness?
Language Models Can Control Their Own Attention
It Takes Two to Match: Co-Evolving Generative Retriever with Reinforcement Learning
EarlyEval: Cheaper Agent Evaluation via Early Outcome Prediction
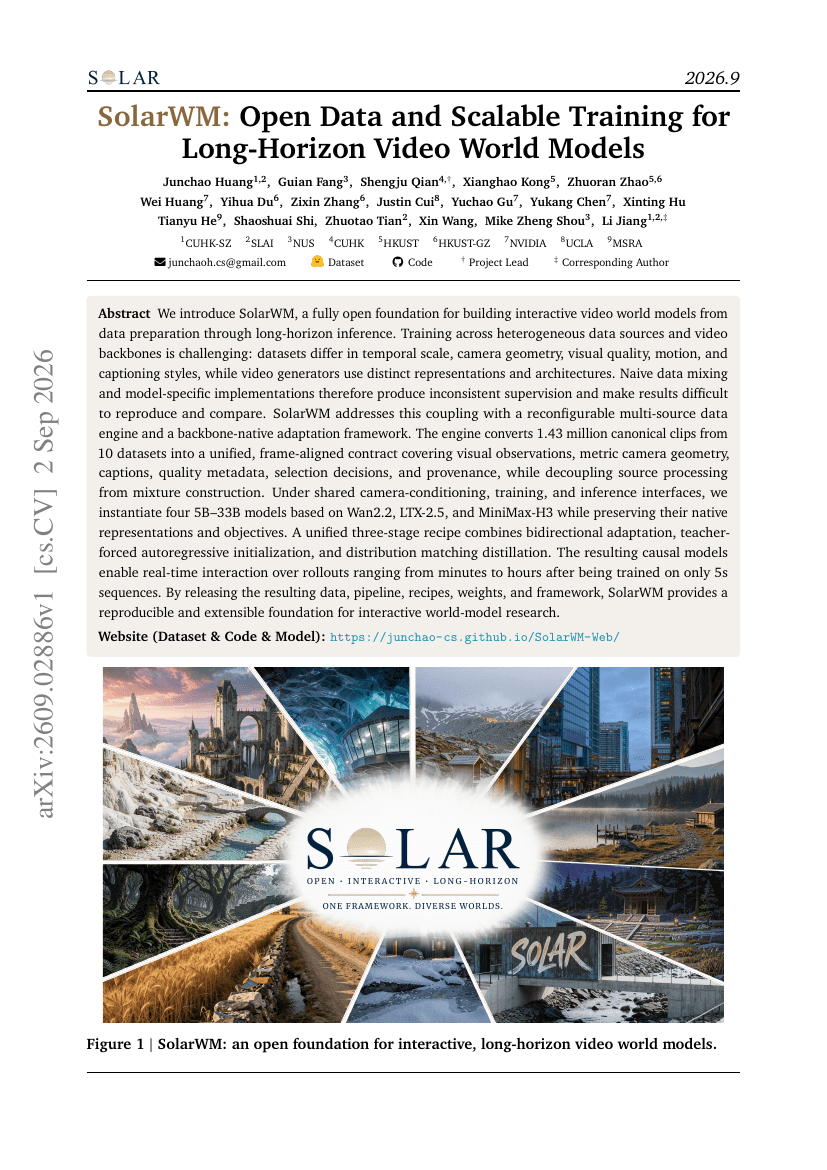
SolarWM: Open Data and Scalable Training for Long-Horizon Video World Models
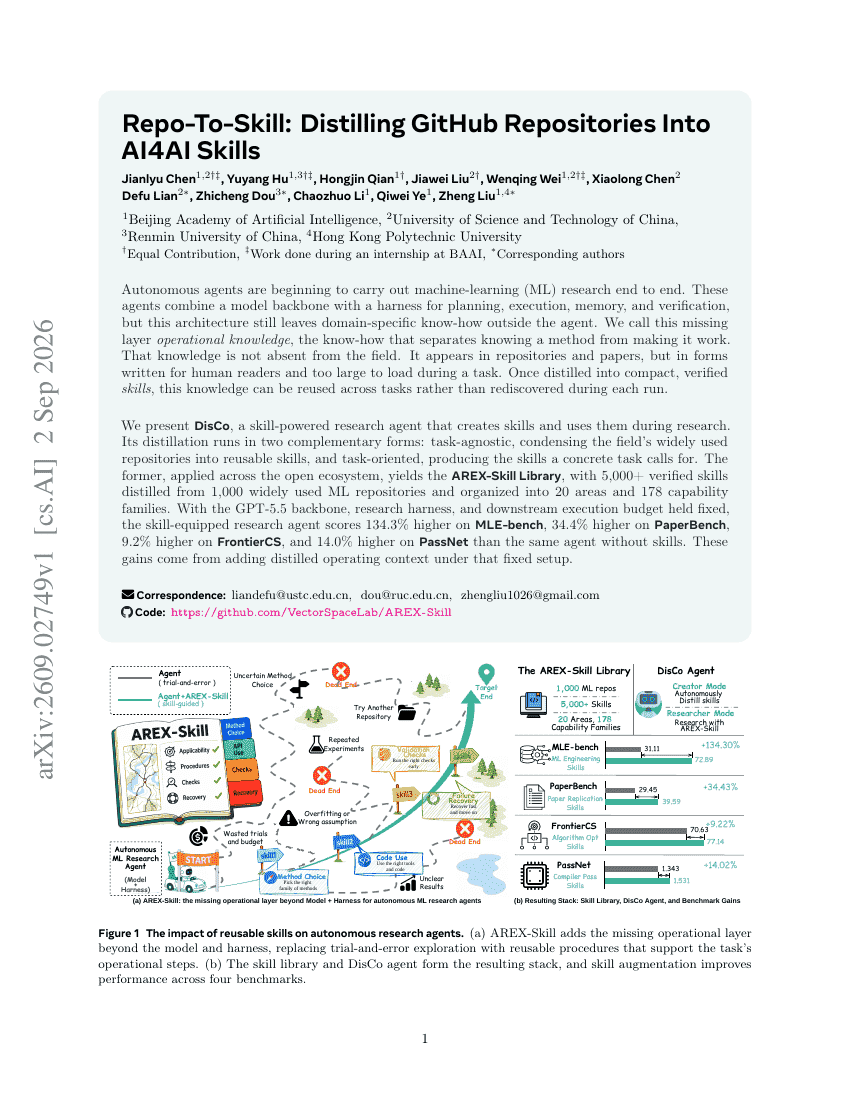
Repo-To-Skill: Distilling GitHub Repositories Into AI4AI Skills
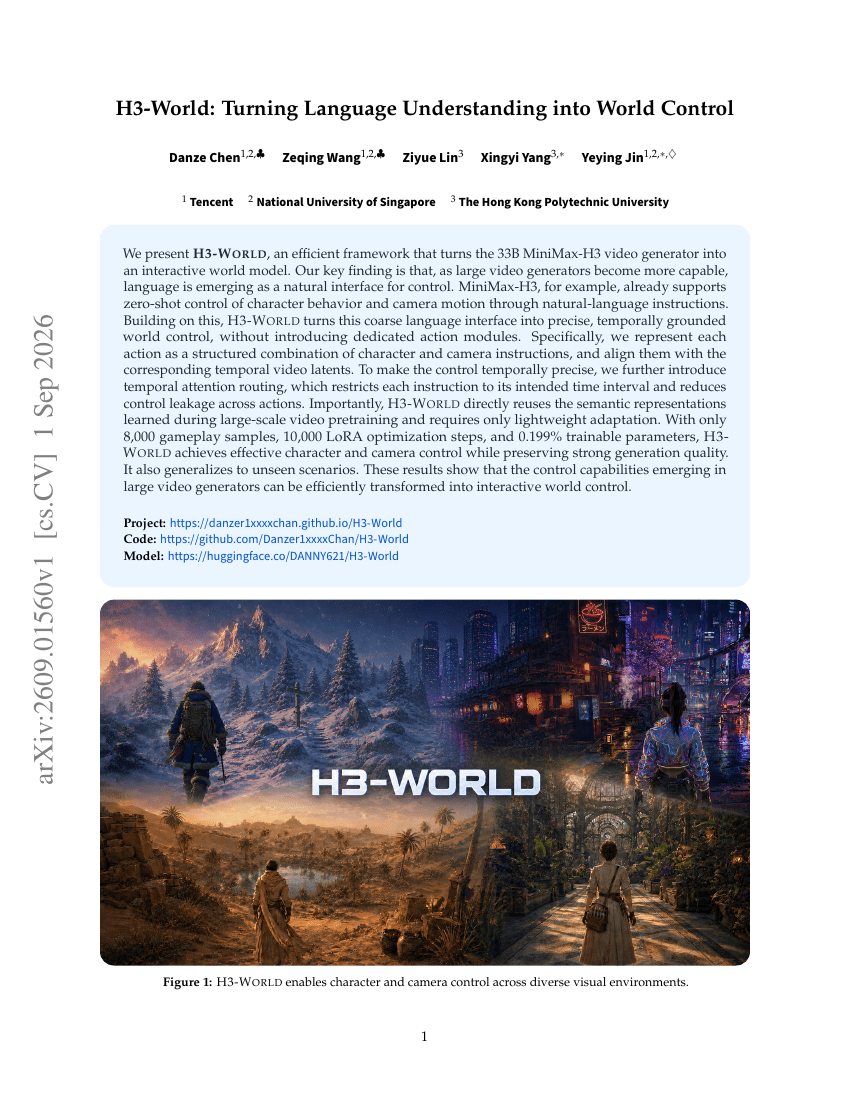
H3-World: Turning Language Understanding into World Control
ZimaBlue: Evolving Generalizable World Action Models through Scalable Video Pre-training
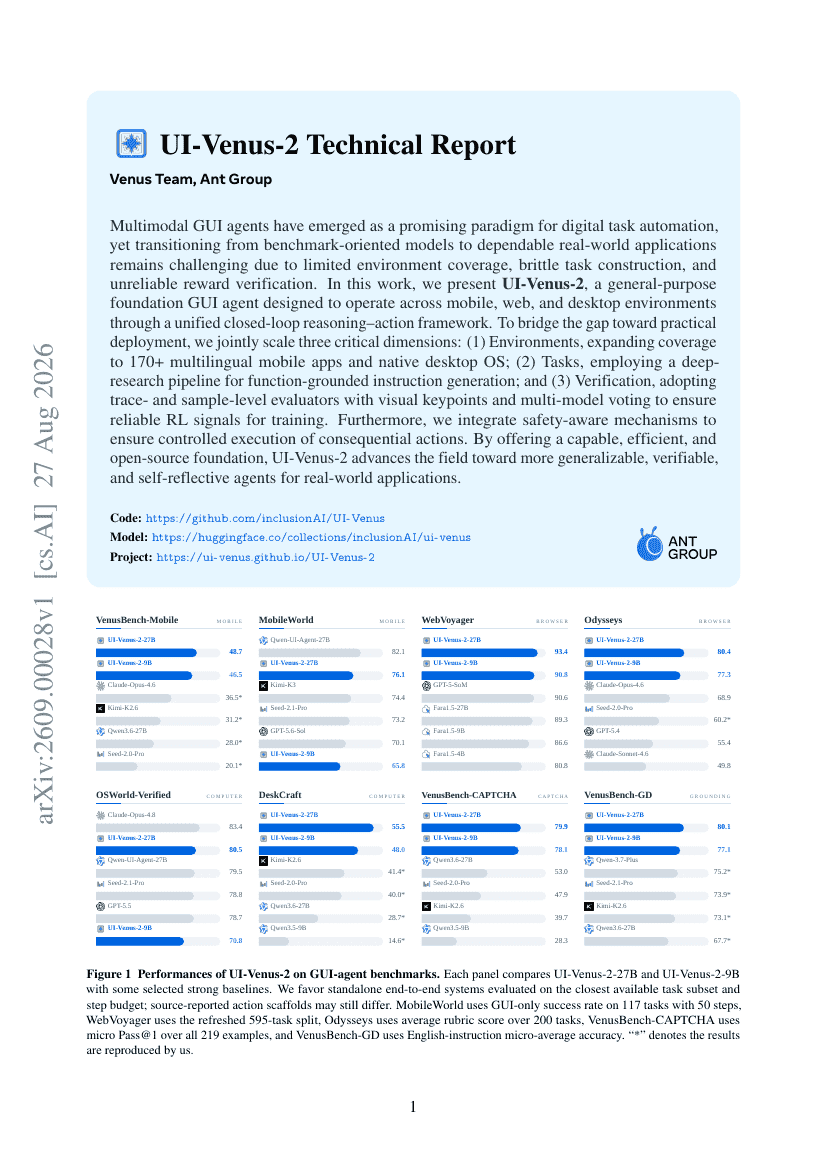
UI-Venus-2: A Large Language Model for GUI Agents
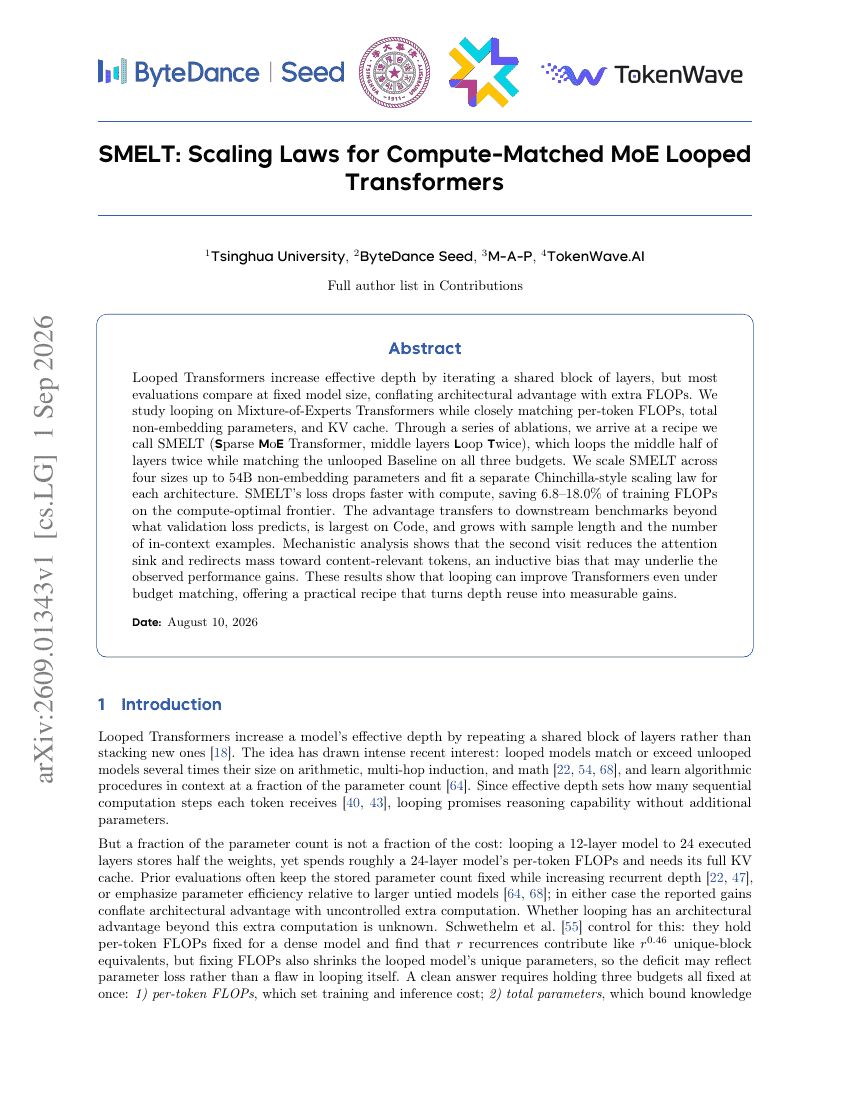
SMELT: Scaling Laws for Compute-Matched MoE Looped Transformers
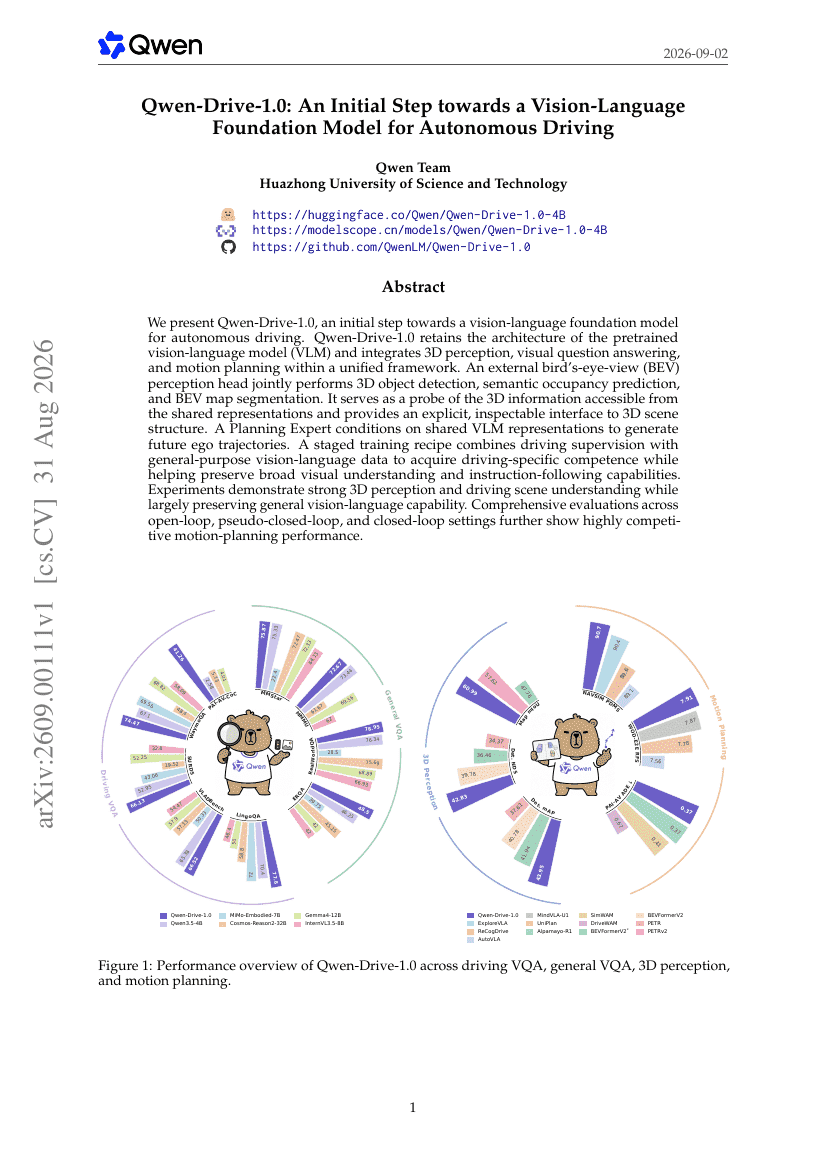
Qwen-Drive-1.0: An Initial Step towards a Vision-Language Foundation Model for Autonomous Driving
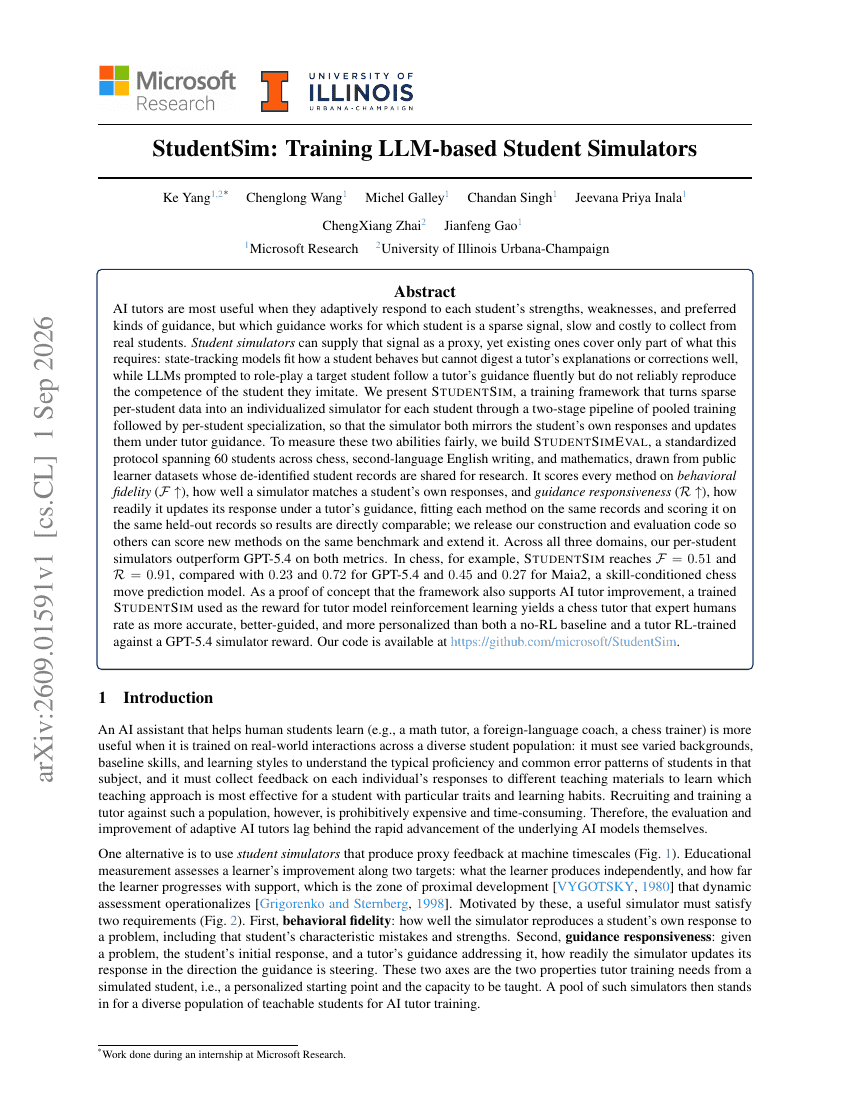
StudentSim: Training LLM-based Student Simulators
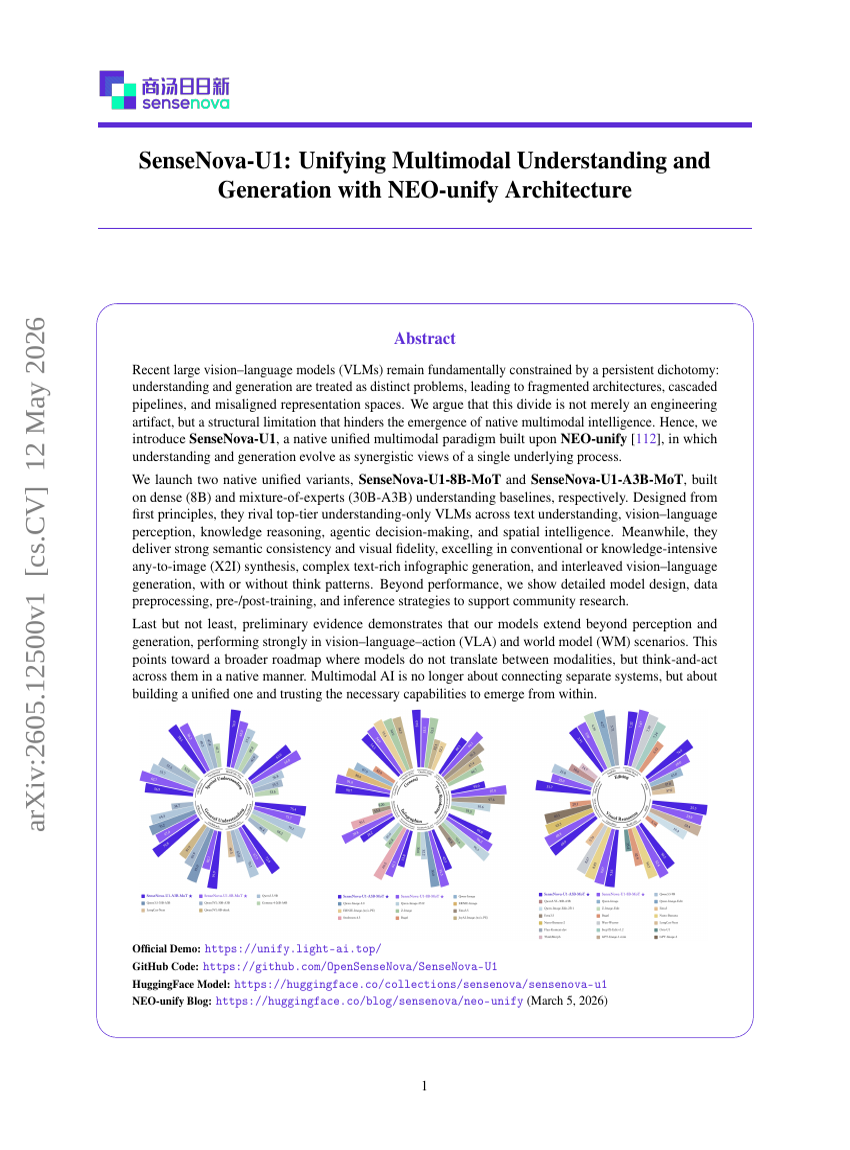
SenseNova-U1: Unifying Multimodal Understanding and Generation with NEO-unify Architecture
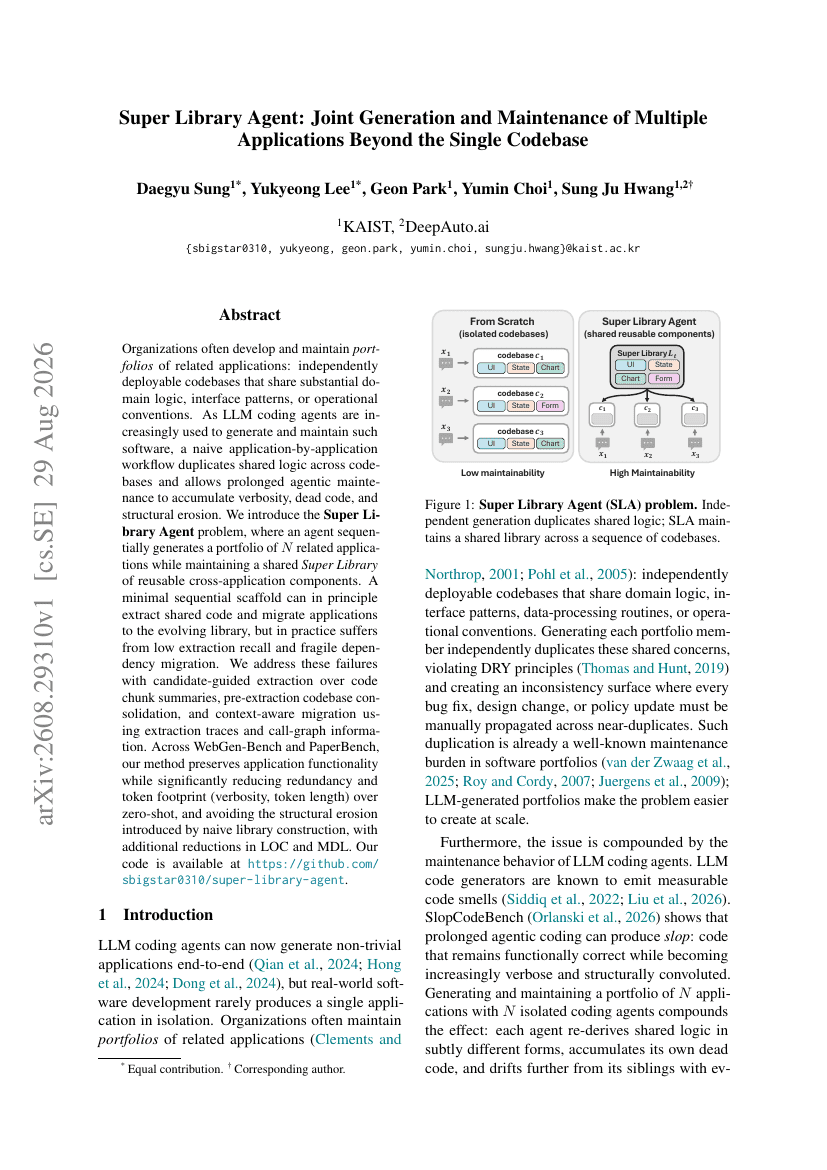
Super Library Agent: Joint Generation and Maintenance of Multiple Applications Beyond the Single Codebase
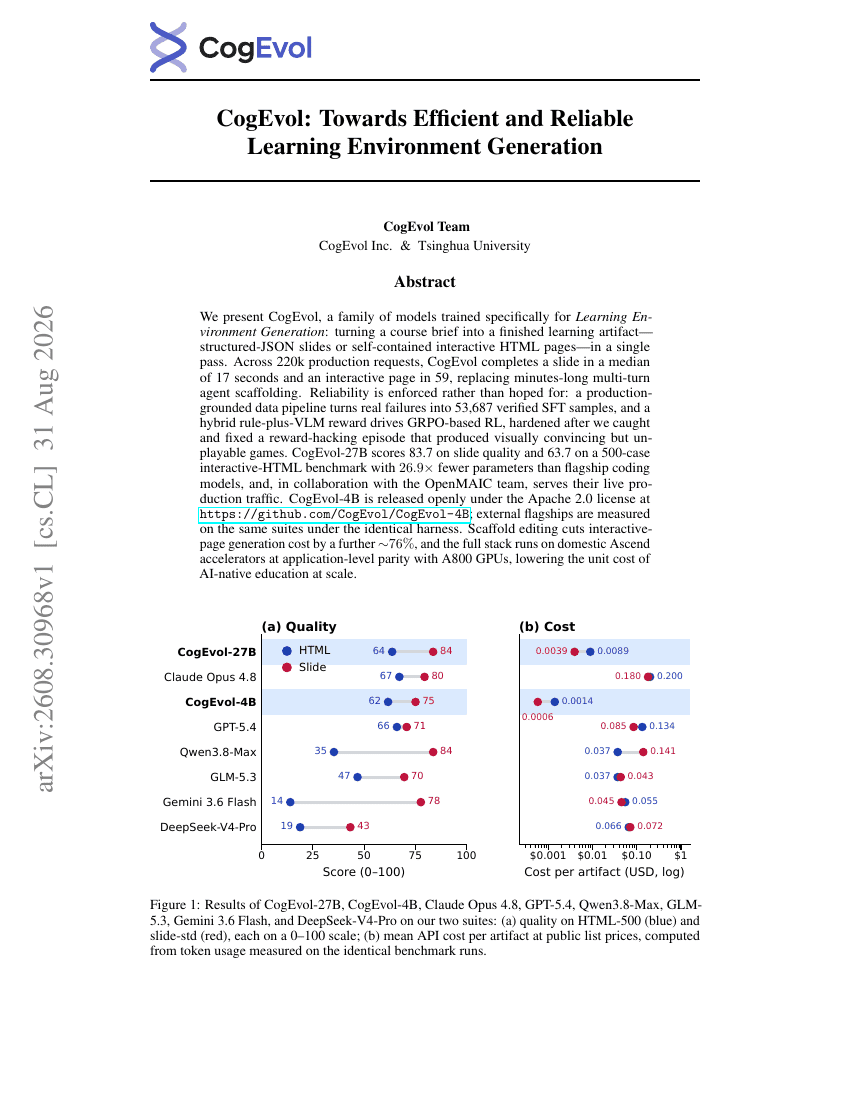
CogEvol: Towards Efficient and Reliable Learning Environment Generation
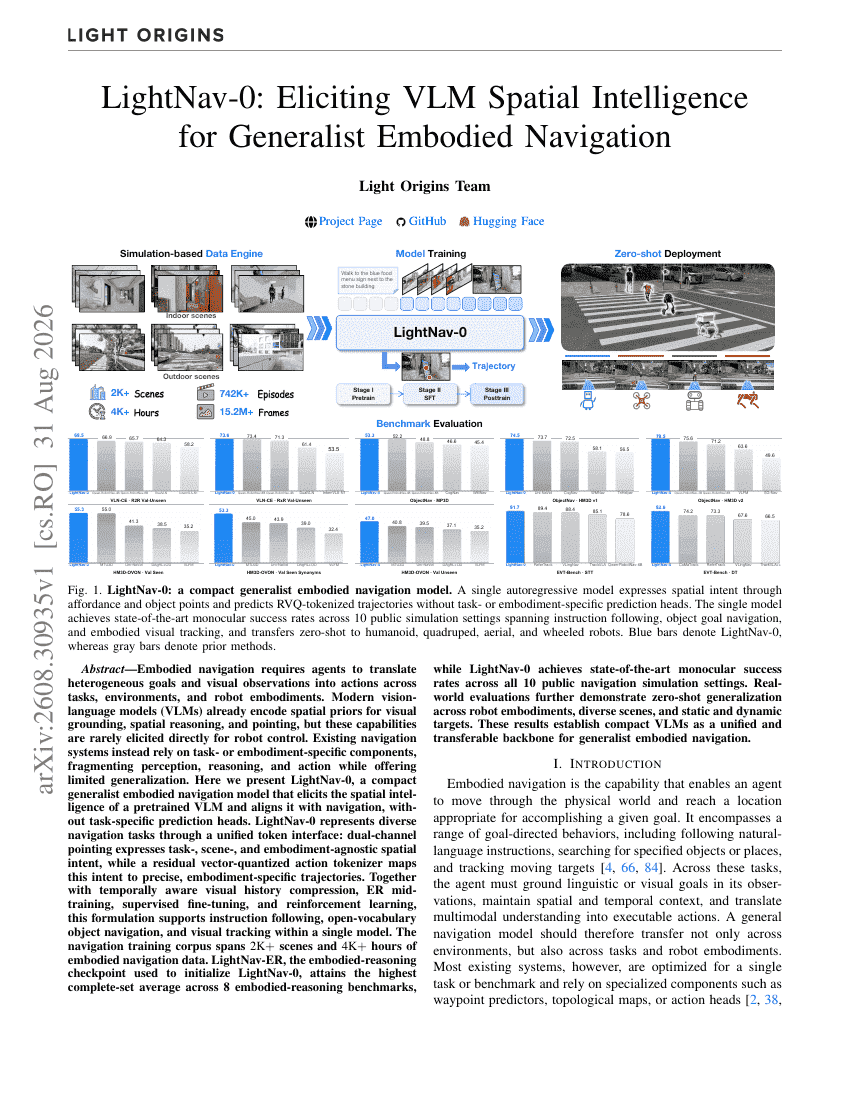
LightNav-0: Eliciting VLM Spatial Intelligence for Generalist Embodied Navigation
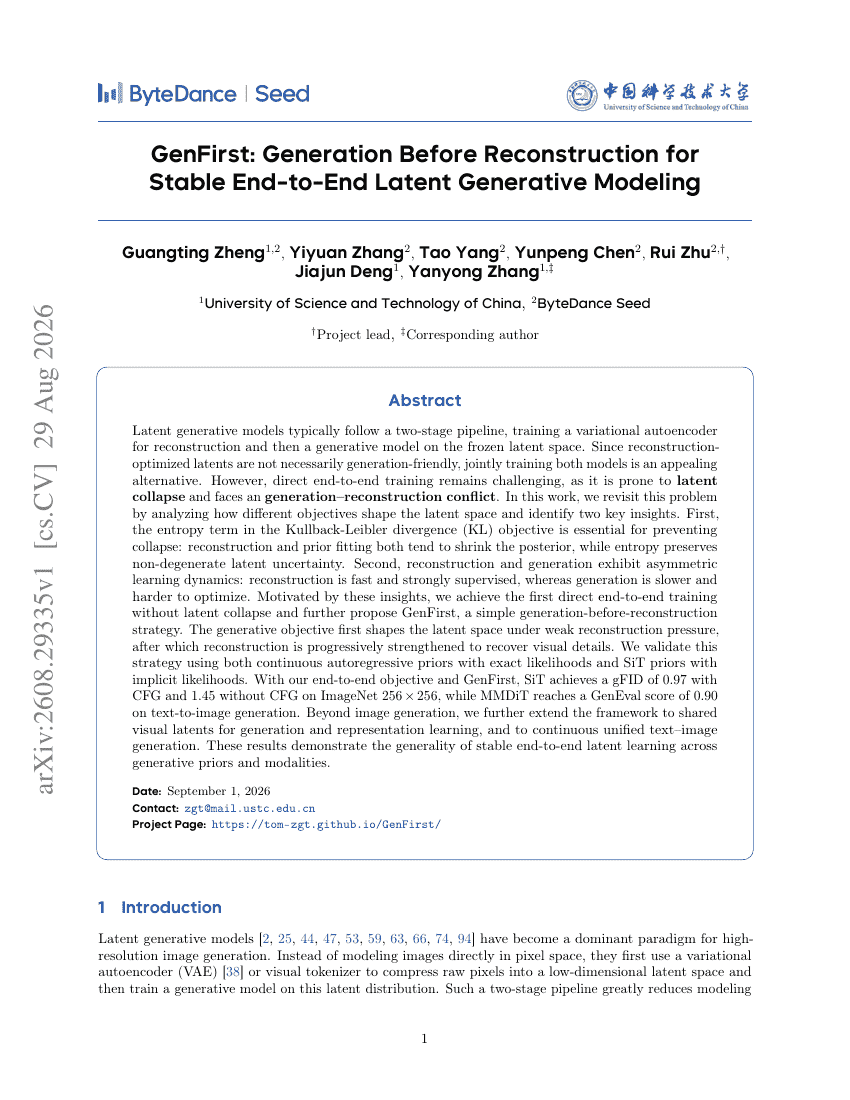
GenFirst: Generation Before Reconstruction for Stable End-to-End Latent Generative Modeling
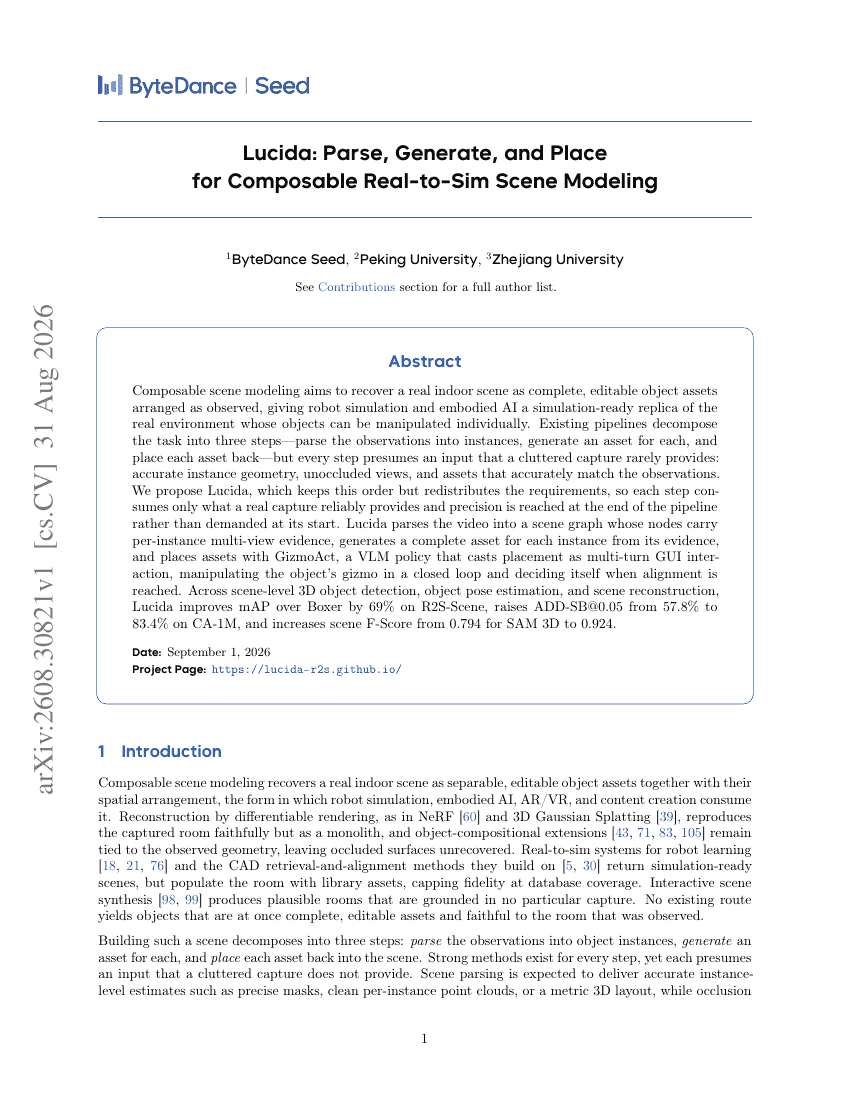
Lucida: Parse, Generate, and Place for Composable Real-to-Sim Scene Modeling
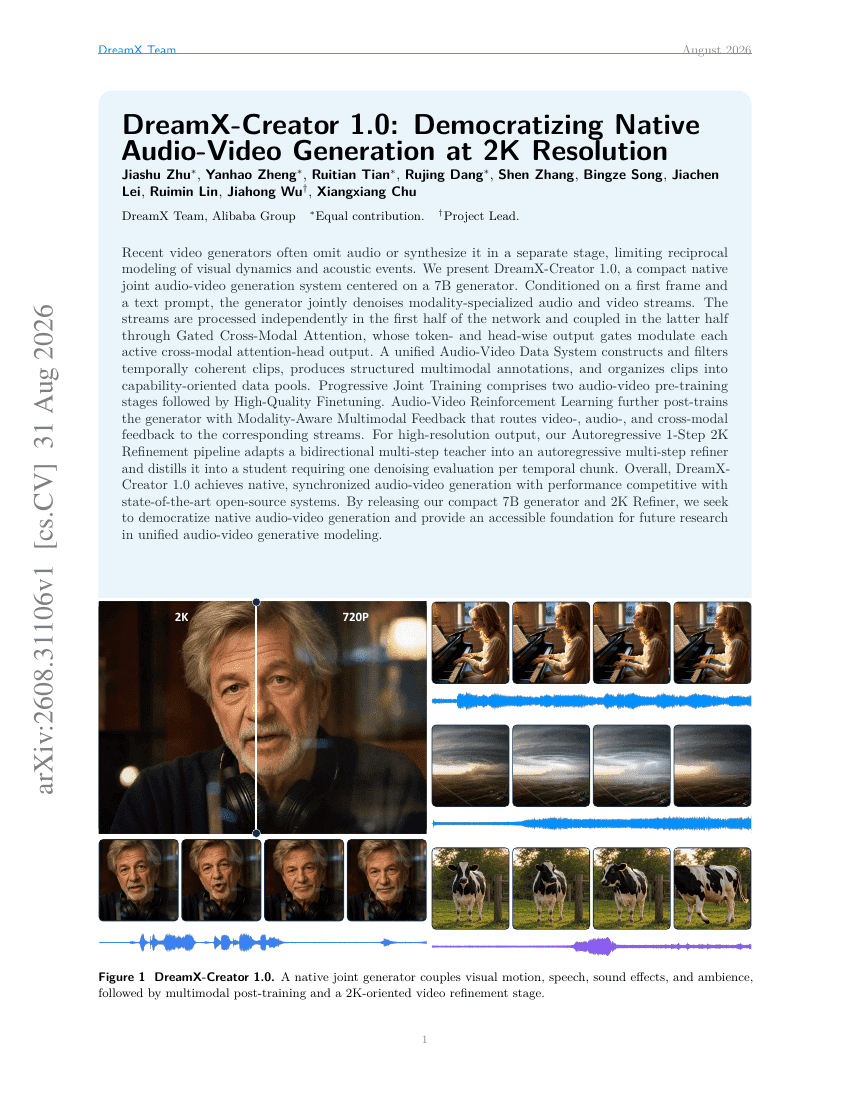
DreamX-Creator 1.0: Democratizing Native Audio-Video Generation at 2K Resolution
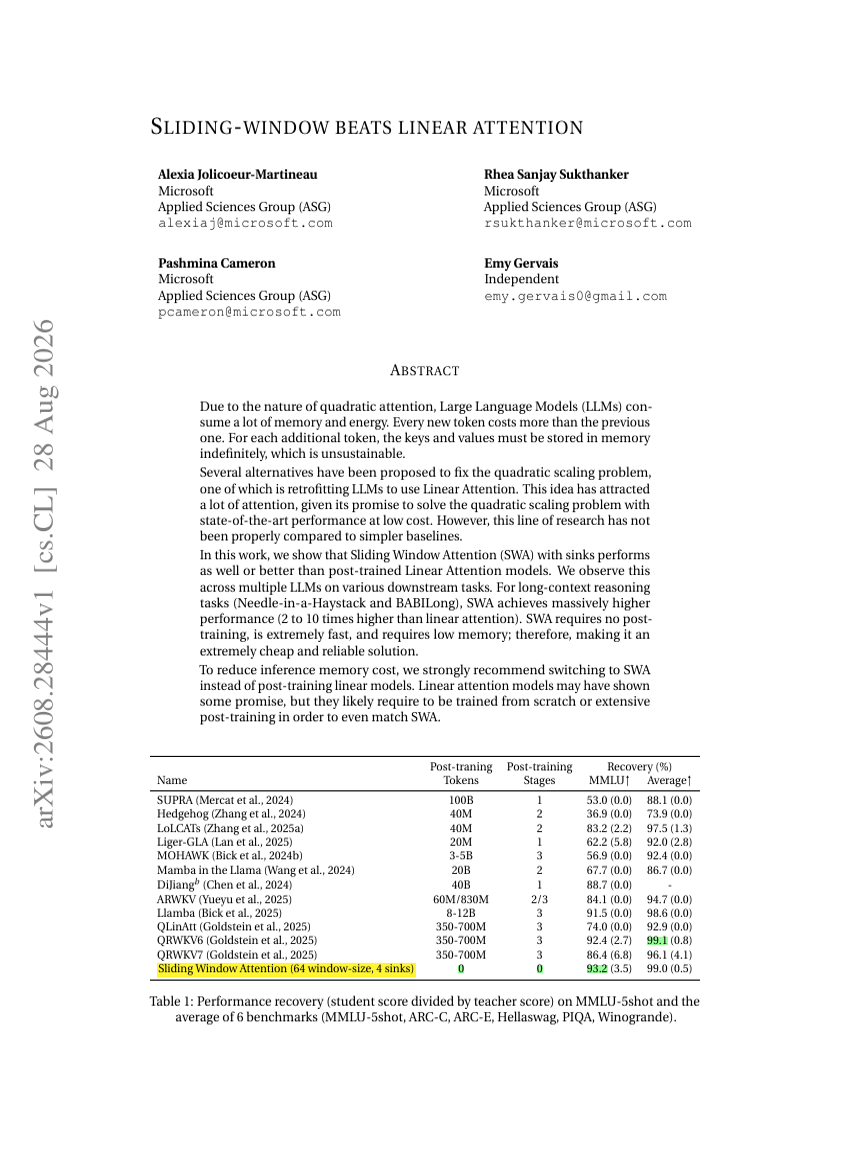
SLIDING-WINDOW BEATS LINEAR ATTENTION