HyperAI
Command Palette
Search for a command to run...
Papers
Daily updated cutting-edge AI research papers to help you keep up with the latest AI trends
papers
AREX-2: Advancing Self-Improving Agents through Long-Horizon Reflective Tasks
FALSE FRONTIERS: DIAGNOSING AND MITIGATING CO-CHEATING IN SELF-EVOLVING SEARCH AGENTS
UNIEVO-VL: AN ON-POLICY SELF-DISTILLATION TRAINING RECIPE FOR MULTIMODAL MODEL SELF-IMPROVEMENT
THE TEACHER IS A DIRECTION, NOT A DESTINATION: EXTRAPOLATING RL-INDUCED REPRESENTATION RESIDUALS IN ON-POLICY DISTILLATION
What Makes World Action Models Generalize? An Empirical Study of Test-Time Future Modeling
MaLiang-Harness: A Programmable Path to Image and Video Generation
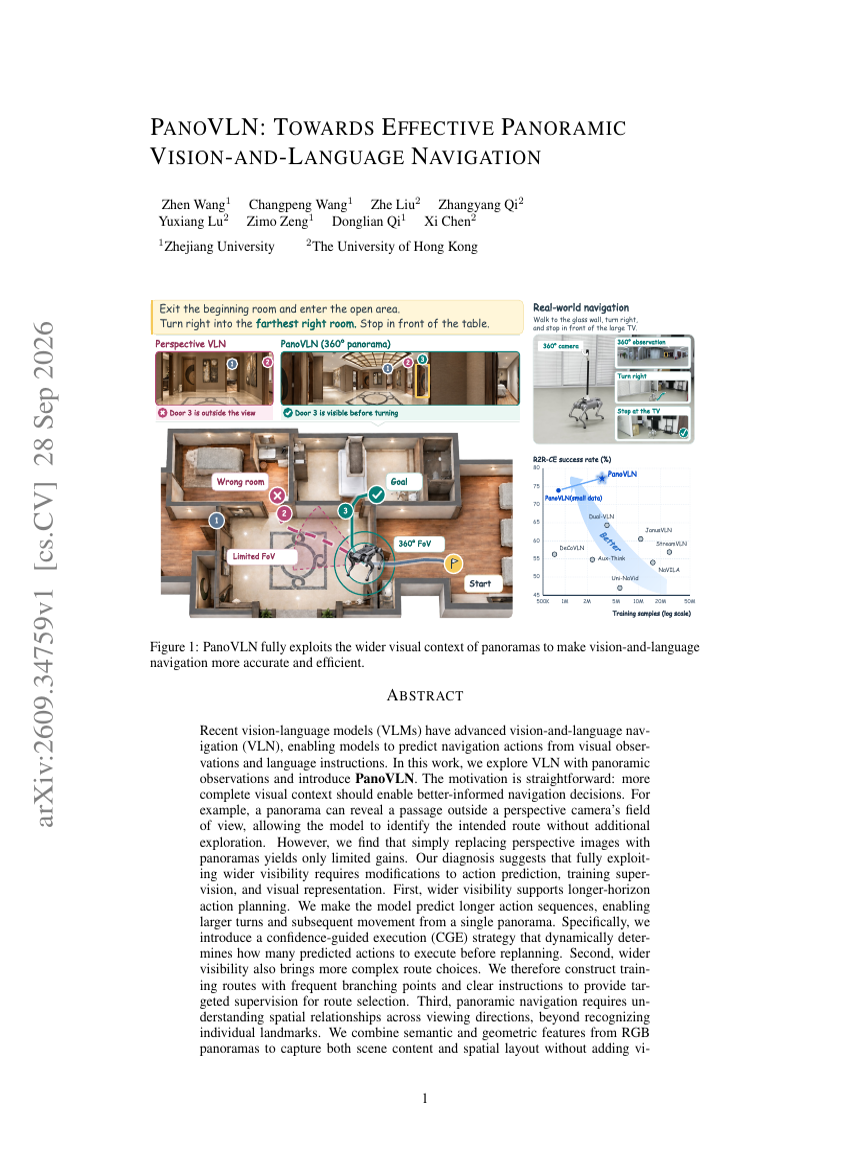
PANOVLN: TOWARDS EFFECTIVE PANORAMIC VISION-AND-LANGUAGE NAVIGATION
VoxMem: Benchmarking Multimodal Memory in Large Audio Language Models
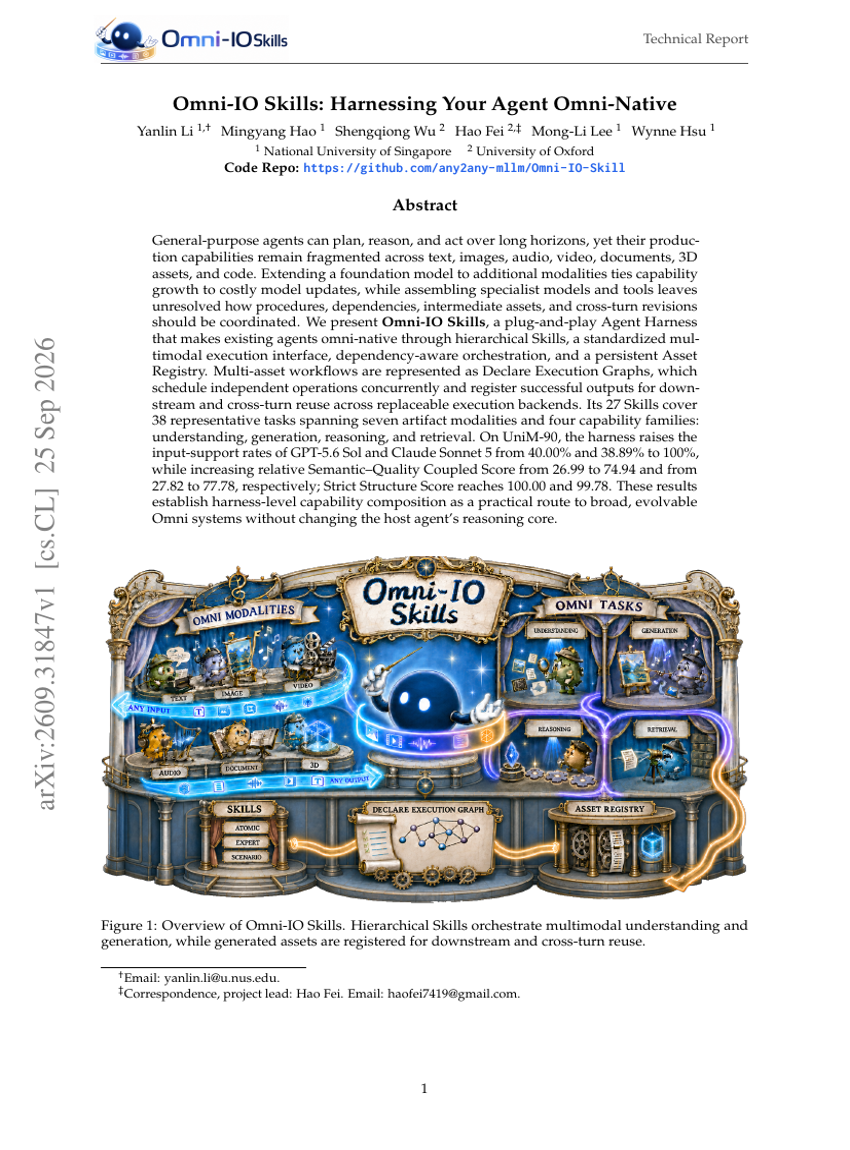
Omni-IO Skills: Harnessing Your Agent Omni-Native
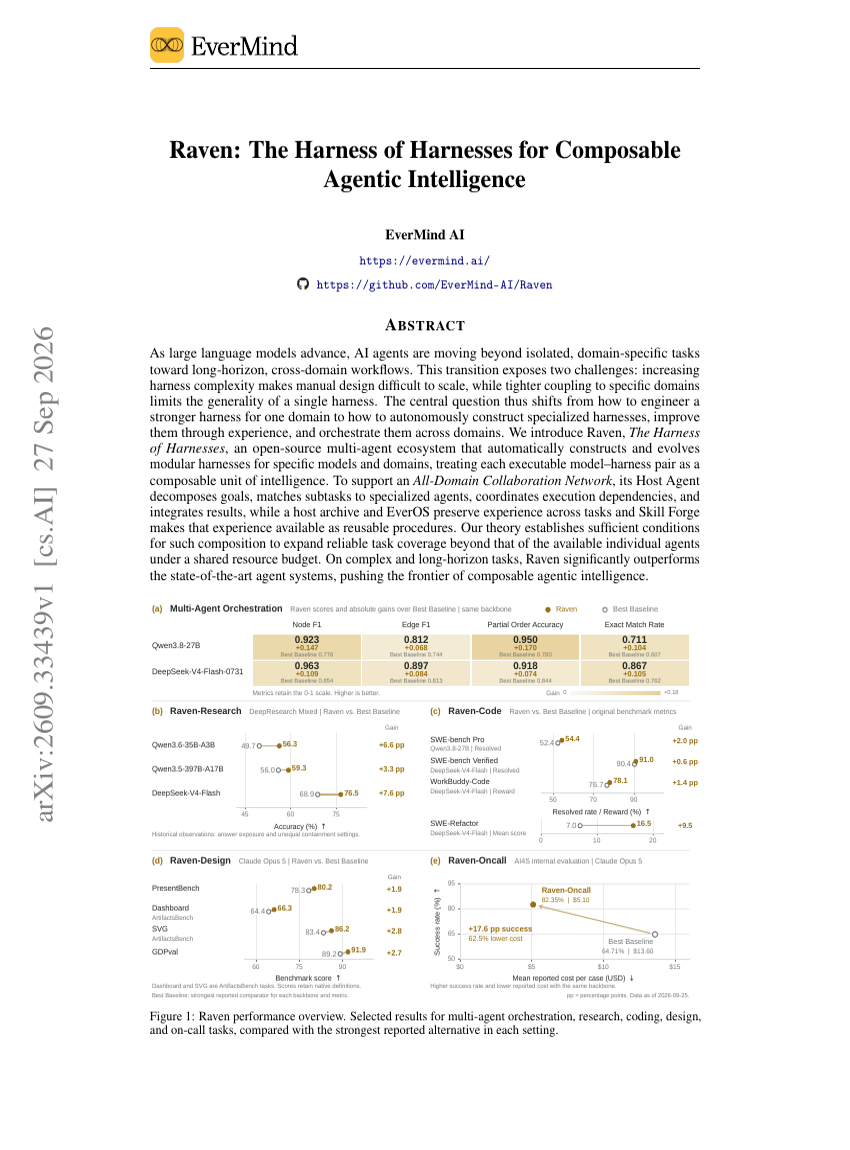
Raven: The Harness of Harnesses for Composable Agentic Intelligence
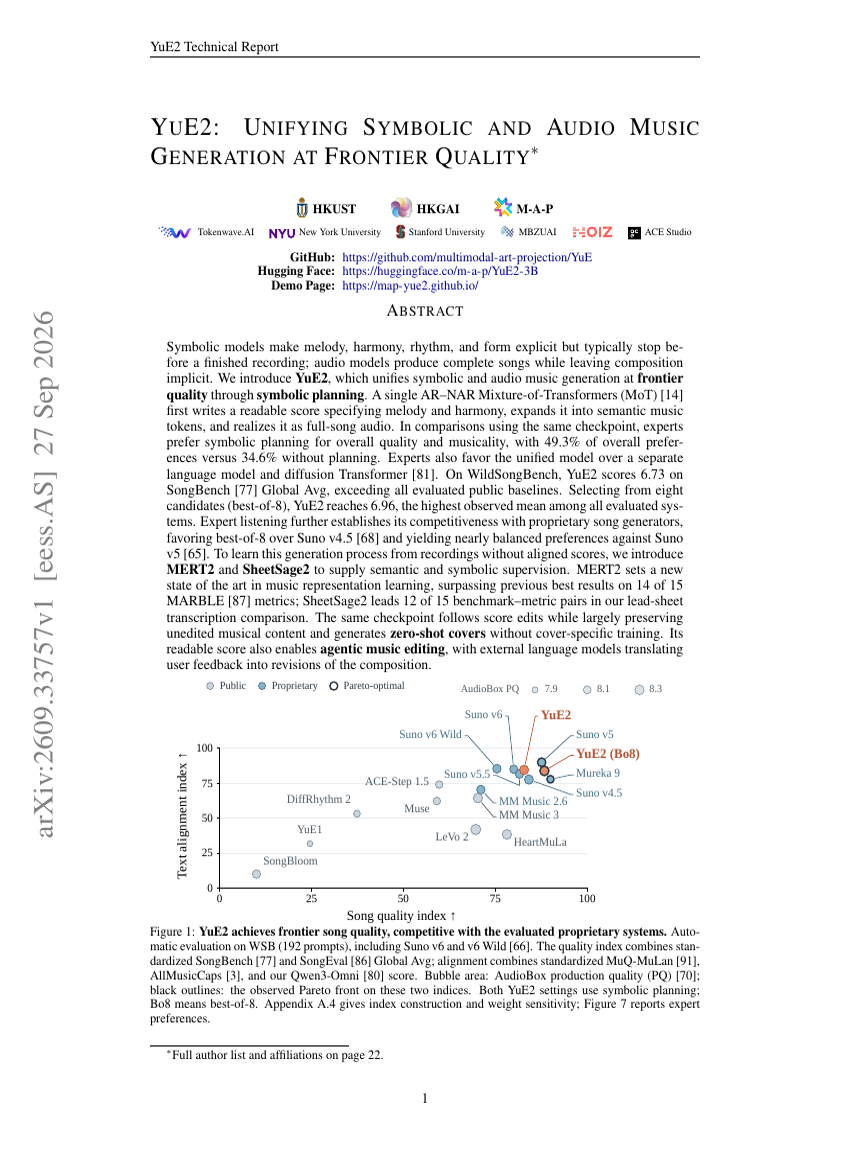
YUE2: UNIFYING SYMBOLIC AND AUDIO MUSIC GENERATION AT FRONTIER QUALITY
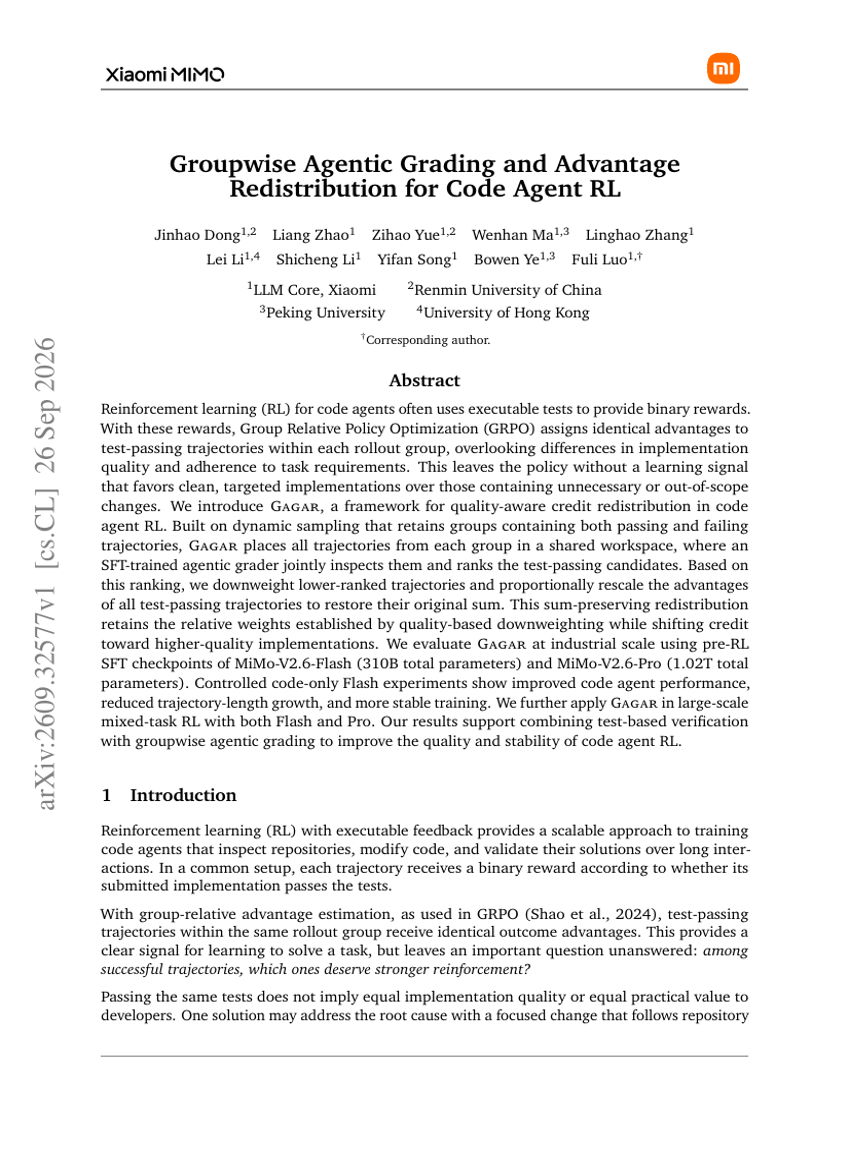
Groupwise Agentic Grading and Advantage Redistribution for Code Agent RL
How Far Are We from Removing the Visual Encoder? Scaling Laws for Encoder-Free Multimodal Pretraining
Duplex-MPE: Benchmarking Multi-Party Interaction in Full-Duplex Dialogue
Post-Training Leaves Behavioral Shadows on Unrelated Decisions
Beyond Teacher Assignment: Domain-Normalized Multi-Teacher On-Policy Distillation
Enhancing Photogrammetric Digital Surface Models with Pretrained Diffusion Models and Multimodal Conditioning
Tactile-JEPA: Topology-Aware Self-Supervised Representation Learning for Distributed Tactile Sensors
InternW0-∆: A World Action Model Bridging Predictive Dynamics and Actions with 20K+ Hours of Open Data
Block Sparse Attention with Log-Linear Complexity
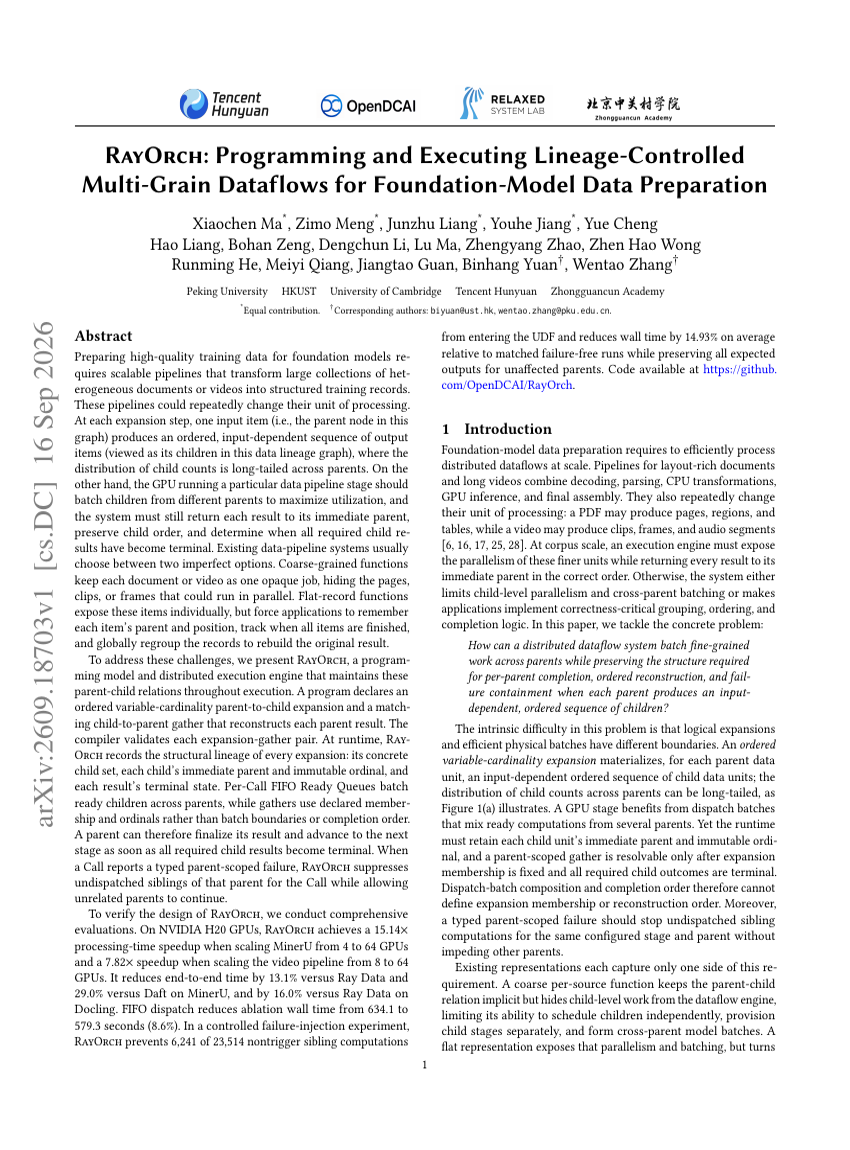
RayOrch: Programming and Executing Lineage-Controlled Multi-Grain Dataflows for Foundation-Model Data Preparation
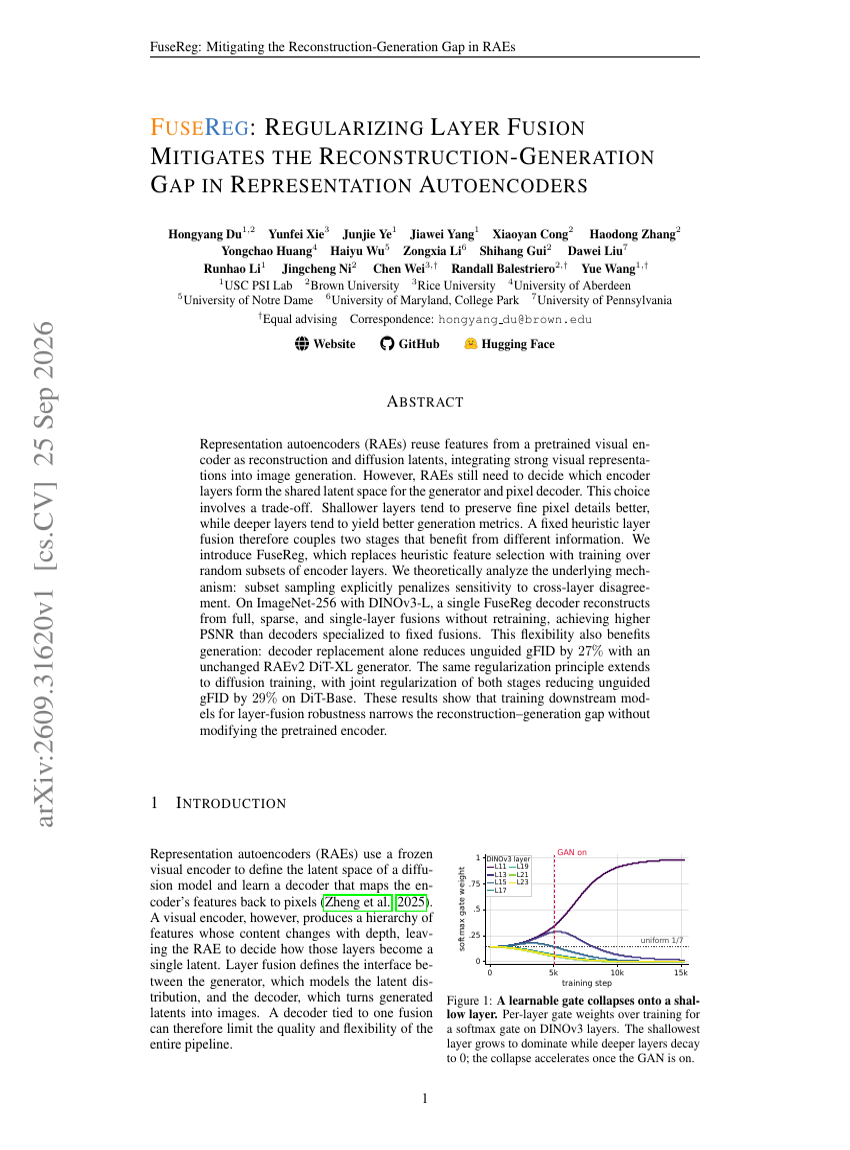
FuseReg: Regularizing Layer Fusion Mitigates the Reconstruction-Generation Gap in Representation Autoencoders
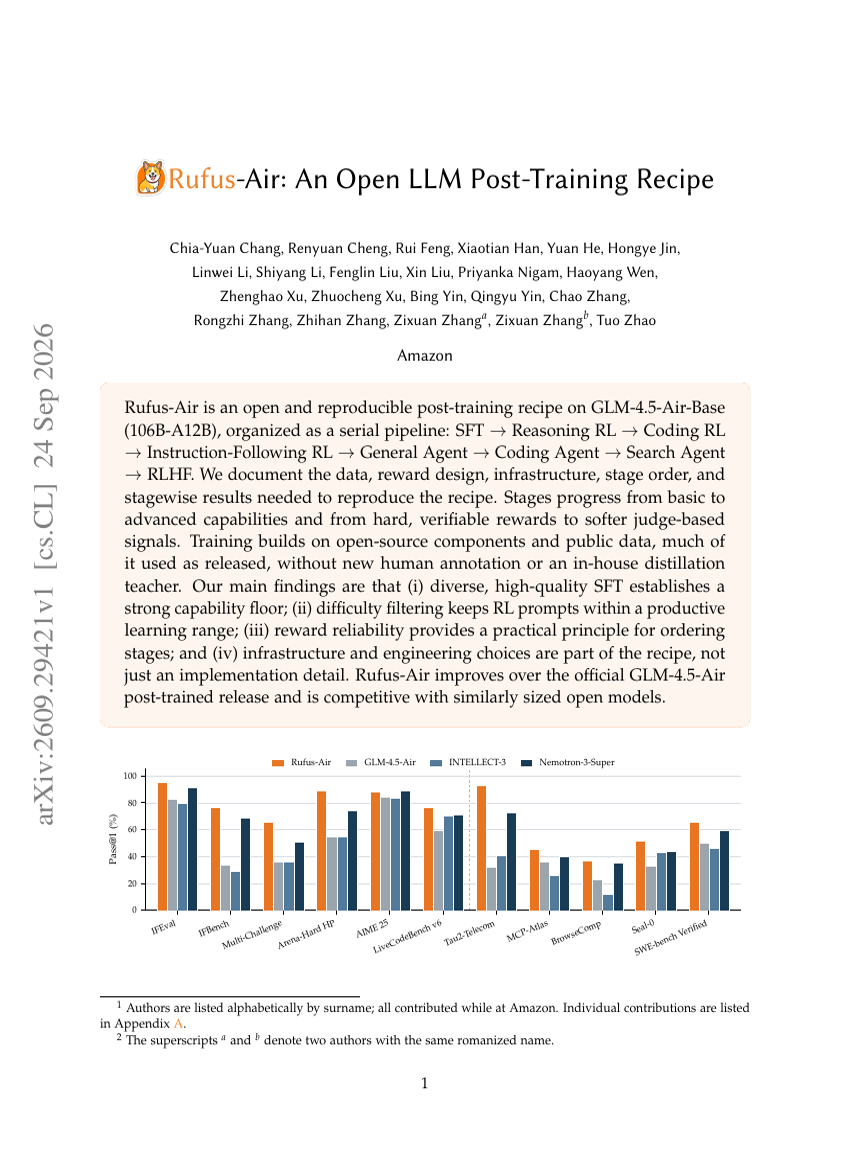
Rufus-Air: An Open LLM Post-Training Recipe
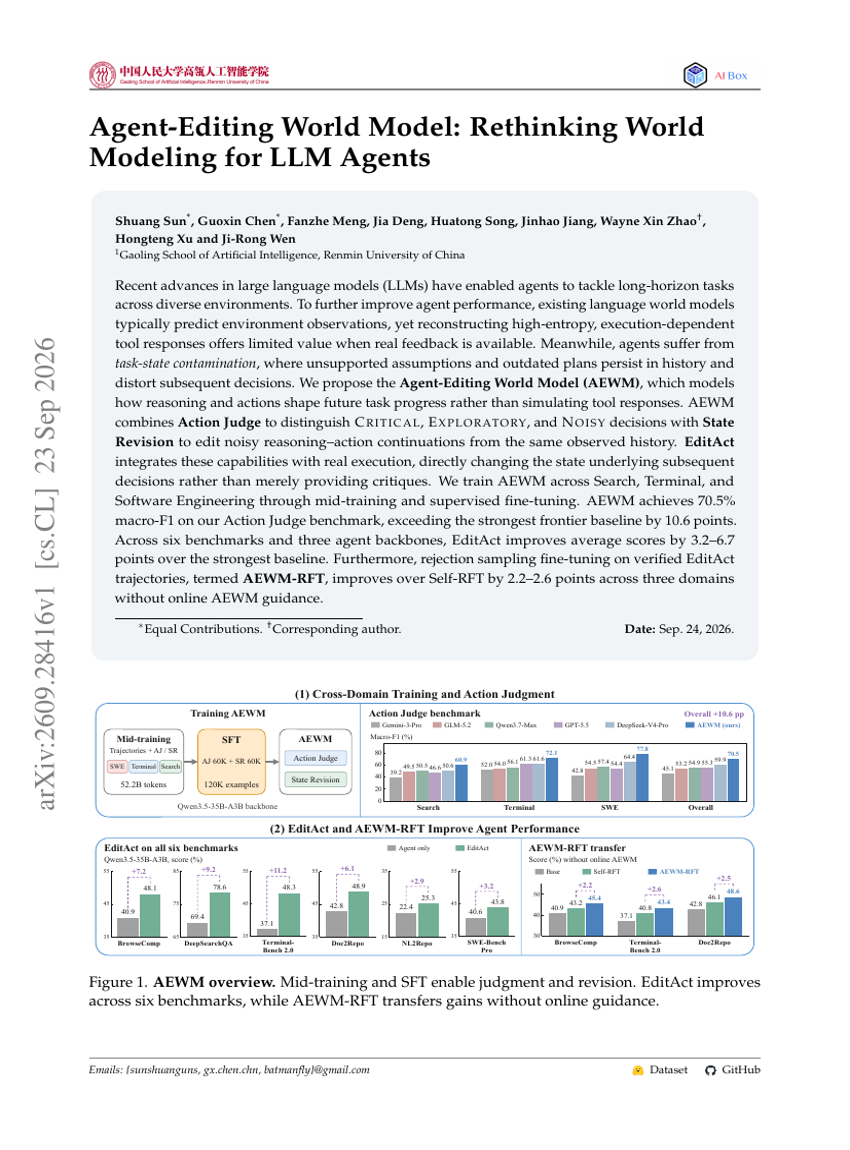
Agent-Editing World Model: Rethinking World Modeling for LLM Agents
OMNIECHO: AUDIO-VISUAL SPATIAL UNDERSTANDING FOR OMNI-MODAL EMBODIED AGENTS
WanPE: Towards Cinematic Prompt Enhancement for Modern Text-to-Video Generation
Your Transformer Can Hold Two Thoughts at Once: Evidence of Linear Superposition in LLMs
Training Object Permanence in World Models
Just-in-Time Memory: Learning to Curate Task-Adaptive Memory for LLM Agents
REWARDVERSE: RUBRIC-GUIDED POLICY OPTIMIZATION FOR VIDEO REWARD MODELING